Your Cohere resume, matched to the job ad
Drop in your resume and it opens next to this job, ready to tailor in one click.
4.8 from 167 in-app reviews
Forward Deployed Engineer, Inference
Cohere · United States
Tailor your resume to this job
No account needed to start.
What Cohere asks for
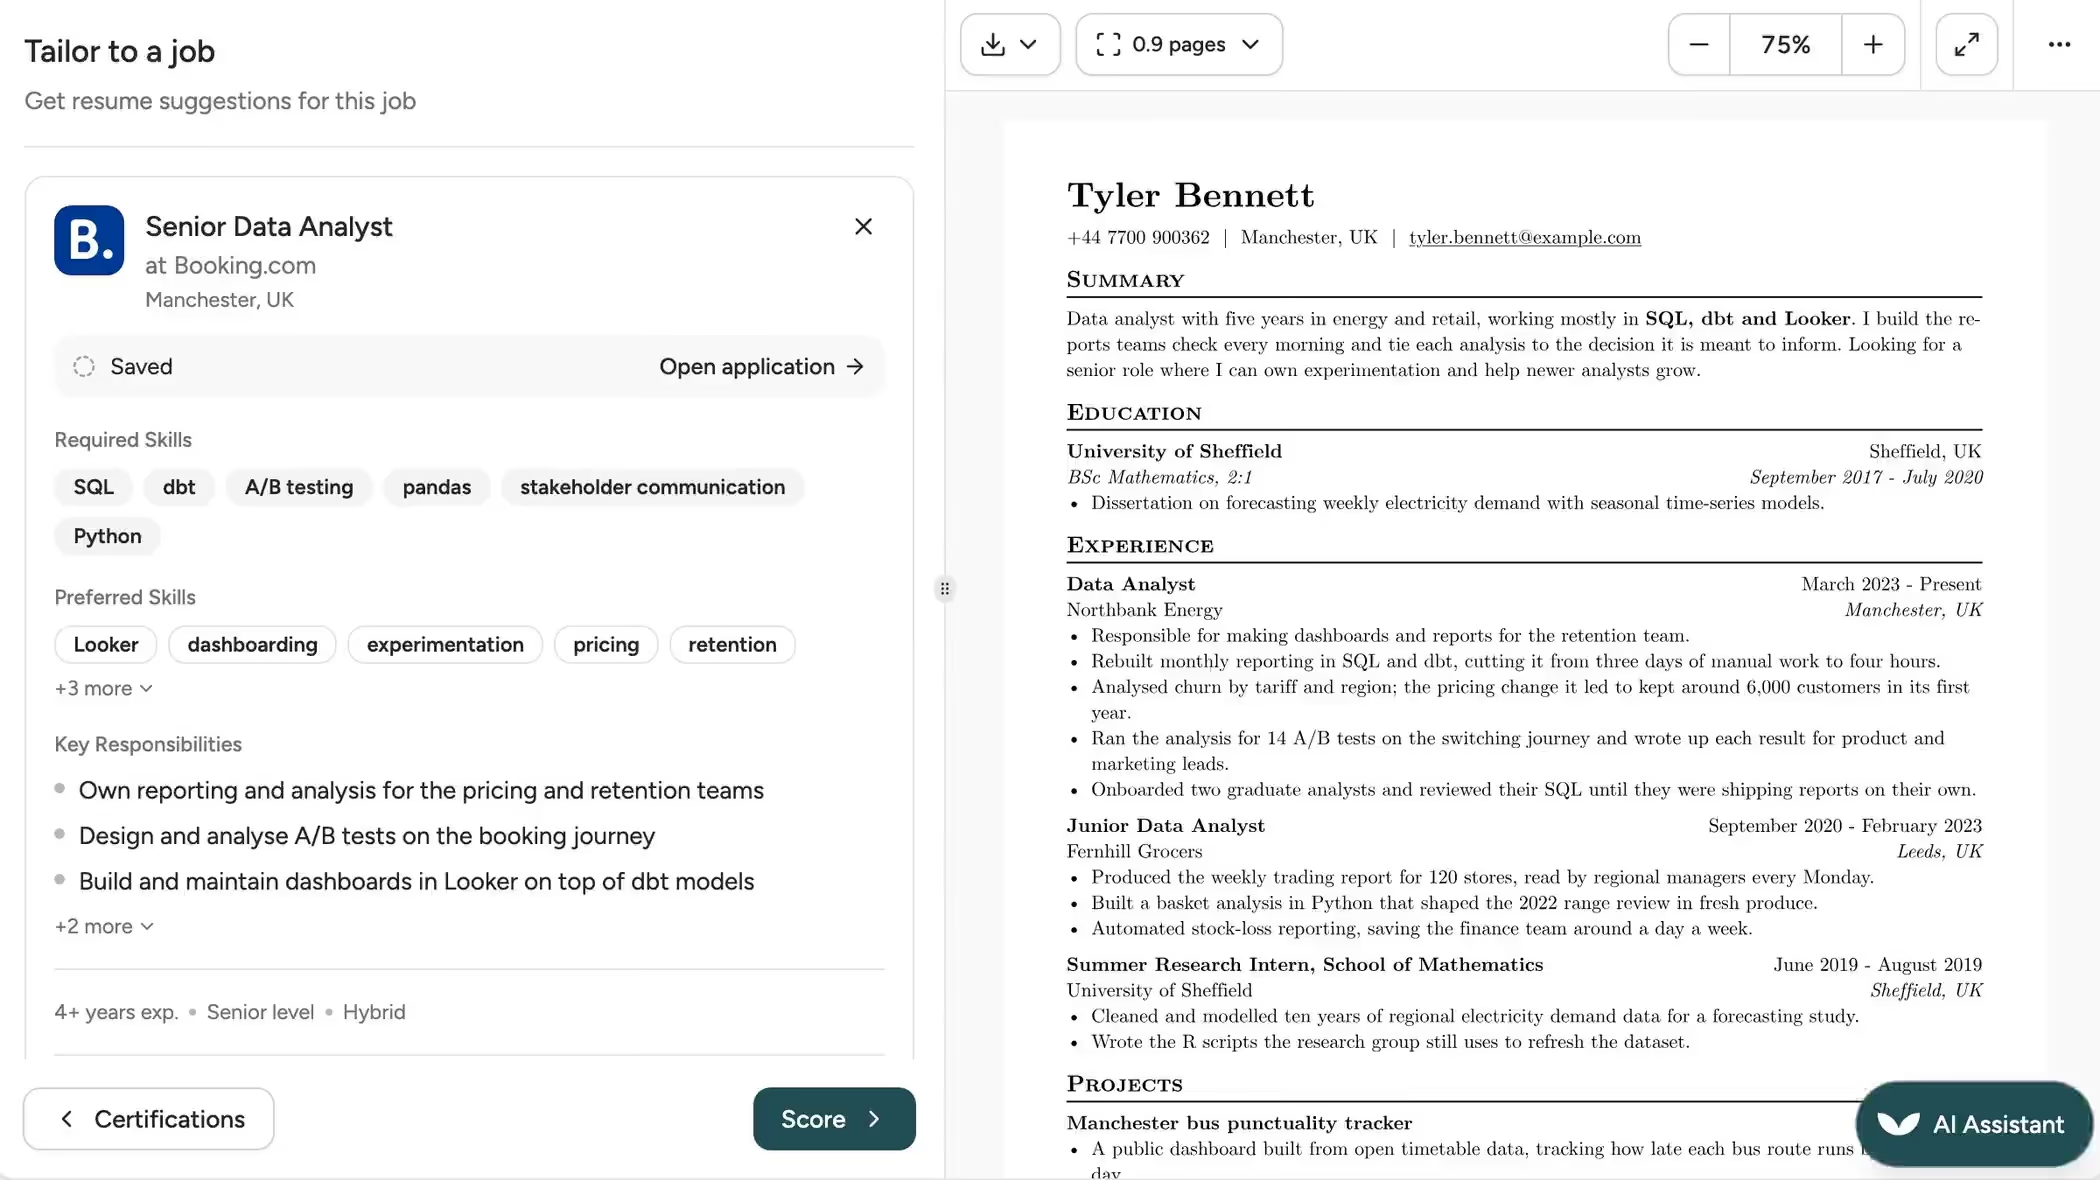
From Cohere's Forward Deployed Engineer, Inference ad, checked 3 Nov 2026.
Production Kubernetes
Deep experience with production Kubernetes, including managing clusters across hybrid or multi-cloud environments such as AWS, Azure, GCP, or OCI.
Inference and model optimization
Hands-on experience with optimization stacks like TensorRT-LLM or vLLM, and understanding how attention and memory phases impact live model performance.
Distributed systems and resilience
Designing topologies for model serving that include multi-tenant architecture, intelligent routing, and failover strategies across multiple datacenters.
Client technical leadership
Leading technical engagements with executive stakeholders and managing the complex politics or blockers inherent in client-side deployments.
Python, Go, or C++
Strong foundations in Python, Go, or C++ to move between data pipelines and infrastructure tuning.
The ad asks for 8 or more years of engineering experience. The role is remote-friendly, with offices in several global cities and a co-working benefit for those not near an office.
How the example answers the ad
Three of the five requirements above, each matched to a line in the example.
Distributed systems and resilience
“Architected a multi-region failover strategy across AWS and Azure that reduced system downtime by 60 percent during regional outages.”
Developing a failover strategy across AWS and Azure regions shows the design of topologies for model serving and resilience.
Inference and model optimization
“Optimized LLM inference stacks using vLLM and TensorRT-LLM, lowering GPU memory consumption by 35 percent for high-demand services.”
Working with vLLM and TensorRT-LLM to reduce GPU memory consumption addresses the optimization of model performance.
Client technical leadership
“Managed cross-functional technical engagements with C-suite executives to align infrastructure capabilities with business goals.”
Collaborating with C-suite executives on infrastructure and business alignment shows technical leadership with executive stakeholders.
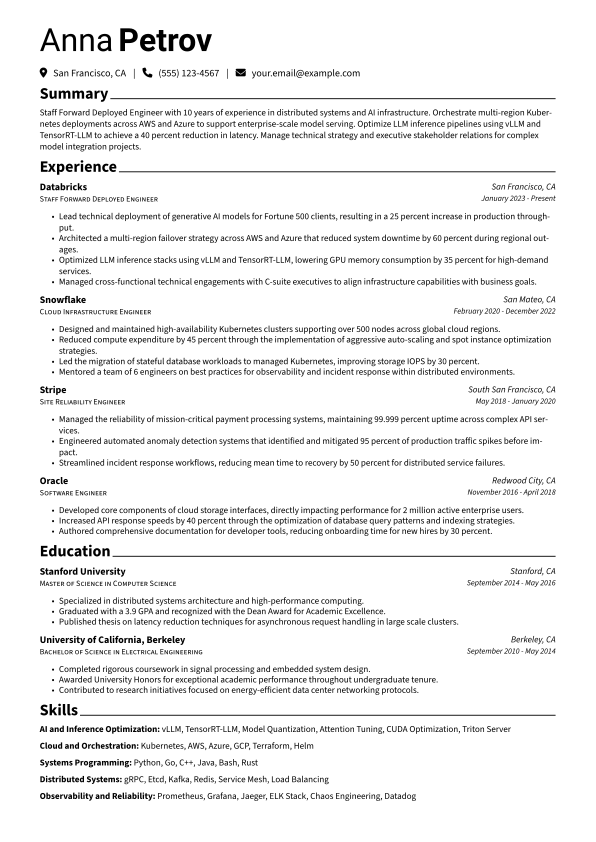
The whole example as text
Anna Petrov · Staff Forward Deployed Engineer
Summary
Staff Forward Deployed Engineer with 10 years of experience in distributed systems and AI infrastructure. Orchestrate multi-region Kubernetes deployments across AWS and Azure to support enterprise-scale model serving. Optimize LLM inference pipelines using vLLM and TensorRT-LLM to achieve a 40 percent reduction in latency. Manage technical strategy and executive stakeholder relations for complex model integration projects.
Experience
Staff Forward Deployed Engineer · Databricks
San Francisco, CA · 2023 - Present
- Lead technical deployment of generative AI models for Fortune 500 clients, resulting in a 25 percent increase in production throughput.
- Architected a multi-region failover strategy across AWS and Azure that reduced system downtime by 60 percent during regional outages.
- Optimized LLM inference stacks using vLLM and TensorRT-LLM, lowering GPU memory consumption by 35 percent for high-demand services.
- Managed cross-functional technical engagements with C-suite executives to align infrastructure capabilities with business goals.
Cloud Infrastructure Engineer · Snowflake
San Mateo, CA · 2020 - 2022
- Designed and maintained high-availability Kubernetes clusters supporting over 500 nodes across global cloud regions.
- Reduced compute expenditure by 45 percent through the implementation of aggressive auto-scaling and spot instance optimization strategies.
- Led the migration of stateful database workloads to managed Kubernetes, improving storage IOPS by 30 percent.
- Mentored a team of 6 engineers on best practices for observability and incident response within distributed environments.
Site Reliability Engineer · Stripe
South San Francisco, CA · 2018 - 2020
- Managed the reliability of mission-critical payment processing systems, maintaining 99.999 percent uptime across complex API services.
- Engineered automated anomaly detection systems that identified and mitigated 95 percent of production traffic spikes before impact.
- Streamlined incident response workflows, reducing mean time to recovery by 50 percent for distributed service failures.
Software Engineer · Oracle
Redwood City, CA · 2016 - 2018
- Developed core components of cloud storage interfaces, directly impacting performance for 2 million active enterprise users.
- Increased API response speeds by 40 percent through the optimization of database query patterns and indexing strategies.
- Authored comprehensive documentation for developer tools, reducing onboarding time for new hires by 30 percent.
Education
Master of Science in Computer Science · Stanford University
Stanford, CA · 2014 - 2016
- Specialized in distributed systems architecture and high-performance computing.
- Graduated with a 3.9 GPA and recognized with the Dean Award for Academic Excellence.
- Published thesis on latency reduction techniques for asynchronous request handling in large scale clusters.
Bachelor of Science in Electrical Engineering · University of California, Berkeley
Berkeley, CA · 2010 - 2014
- Completed rigorous coursework in signal processing and embedded system design.
- Awarded University Honors for exceptional academic performance throughout undergraduate tenure.
- Contributed to research initiatives focused on energy-efficient data center networking protocols.
Skills
Frequently asked questions
Is the example from an employee?
No. It is an AI-written example for this ad, made to show how a resume can answer it.
Do I need every listed qualification?
No. The ad states that if your experience does not line up exactly with every requirement, you are still encouraged to apply.
What hardware will I work with?
You will collaborate with clients to run and support models on next-generation accelerators, including GPUs, TPUs, AMD, and custom ASICs.
Where do I apply?
On the official Cohere posting, through the job link on this page.
What happens when I tailor my resume here?
Your resume opens in the editor next to this job. Tailor it in one click, then keep or discard the edits. You only need an account to download.