Your Datadog resume, matched to the job ad
Drop in your resume and it opens next to this job, ready to tailor in one click.
4.8 from 167 in-app reviews
Senior Software Engineer
Datadog · Boston, Massachusetts, USA; New York, New York, USA
Tailor your resume to this job
No account needed to start.
What Datadog asks for
From Datadog's Senior Software Engineer ad, checked 3 Nov 2026.
Scaling and high traffic systems
At least 6 years of experience designing systems and solving bottlenecks for services that handle high traffic volume.
AI backend engineering
Building AI backend systems while managing the balance between output quality, infrastructure costs, and response latency.
Production service ownership
Taking responsibility for services in production, including fixing urgent issues and rolling out features using flags.
Redis, Cassandra, and Kafka
Practical experience with distributed systems and data tools like Redis, Cassandra, or Kafka, and building data pipelines.
Go, C, and Python
Significant expertise in programming languages, with a preference for Go, C, or Python to build simple, high performance code.
The ad asks for 6 or more years of experience and a BS, MS, or PhD in a scientific field or equivalent experience. Based in Boston or New York City.
How the example answers the ad
Four of the five requirements above, each matched to a line in the example.
AI backend engineering
“Integrated LLM outputs into production workflows while maintaining a strict 150ms response latency threshold.”
Handling LLM outputs within a 150ms latency limit shows the balance between output quality and response speed required for AI backend engineering.
Go, C, and Python
“Optimized C-based data ingestion modules, achieving a 15 percent reduction in total CPU cycle usage per request.”
A 15 percent reduction in CPU usage through optimization of C modules shows the high performance code expertise required for programming languages.
Production service ownership
“Deployed 12 critical features via feature flags to mitigate production risk and decrease incident response time by 40 percent.”
Using feature flags for 12 features and decreasing incident response times shows production service ownership.
Redis, Cassandra, and Kafka
“Scaled telemetry processing pipelines to handle 2TB of log data daily using customized Kafka consumers.”
Custom Kafka consumers and 2TB of daily logs show practical experience with distributed data systems and data pipelines.
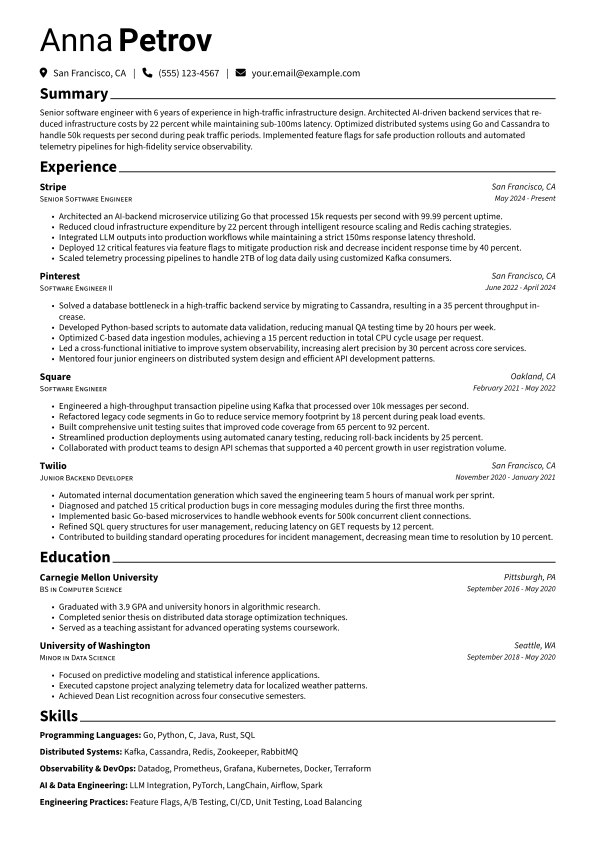
The whole example as text
Anna Petrov · Senior Software Engineer
Summary
Senior software engineer with 6 years of experience in high-traffic infrastructure design. Architected AI-driven backend services that reduced infrastructure costs by 22 percent while maintaining sub-100ms latency. Optimized distributed systems using Go and Cassandra to handle 50k requests per second during peak traffic periods. Implemented feature flags for safe production rollouts and automated telemetry pipelines for high-fidelity service observability.
Experience
Senior Software Engineer · Stripe
San Francisco, CA · 2024 - Present
- Architected an AI-backend microservice utilizing Go that processed 15k requests per second with 99.99 percent uptime.
- Reduced cloud infrastructure expenditure by 22 percent through intelligent resource scaling and Redis caching strategies.
- Integrated LLM outputs into production workflows while maintaining a strict 150ms response latency threshold.
- Deployed 12 critical features via feature flags to mitigate production risk and decrease incident response time by 40 percent.
- Scaled telemetry processing pipelines to handle 2TB of log data daily using customized Kafka consumers.
Software Engineer II · Pinterest
San Francisco, CA · 2022 - 2024
- Solved a database bottleneck in a high-traffic backend service by migrating to Cassandra, resulting in a 35 percent throughput increase.
- Developed Python-based scripts to automate data validation, reducing manual QA testing time by 20 hours per week.
- Optimized C-based data ingestion modules, achieving a 15 percent reduction in total CPU cycle usage per request.
- Led a cross-functional initiative to improve system observability, increasing alert precision by 30 percent across core services.
- Mentored four junior engineers on distributed system design and efficient API development patterns.
Software Engineer · Square
Oakland, CA · 2021 - 2022
- Engineered a high-throughput transaction pipeline using Kafka that processed over 10k messages per second.
- Refactored legacy code segments in Go to reduce service memory footprint by 18 percent during peak load events.
- Built comprehensive unit testing suites that improved code coverage from 65 percent to 92 percent.
- Streamlined production deployments using automated canary testing, reducing roll-back incidents by 25 percent.
- Collaborated with product teams to design API schemas that supported a 40 percent growth in user registration volume.
Junior Backend Developer · Twilio
San Francisco, CA · 2020 - 2021
- Automated internal documentation generation which saved the engineering team 5 hours of manual work per sprint.
- Diagnosed and patched 15 critical production bugs in core messaging modules during the first three months.
- Implemented basic Go-based microservices to handle webhook events for 500k concurrent client connections.
- Refined SQL query structures for user management, reducing latency on GET requests by 12 percent.
- Contributed to building standard operating procedures for incident management, decreasing mean time to resolution by 10 percent.
Education
BS in Computer Science · Carnegie Mellon University
Pittsburgh, PA · 2016 - 2020
- Graduated with 3.9 GPA and university honors in algorithmic research.
- Completed senior thesis on distributed data storage optimization techniques.
- Served as a teaching assistant for advanced operating systems coursework.
Minor in Data Science · University of Washington
Seattle, WA · 2018 - 2020
- Focused on predictive modeling and statistical inference applications.
- Executed capstone project analyzing telemetry data for localized weather patterns.
- Achieved Dean List recognition across four consecutive semesters.
Skills
Frequently asked questions
Is the example from an employee?
No. It is an AI-written example for this ad, made to show how a resume can answer it.
Do I need to meet every requirement to apply?
No. The ad states that they understand not everyone will meet all the qualifications on day one and encourages those passionate about technology to apply anyway.
What kind of experience do I need with AI tools?
You should be able to use AI coding tools in your daily work and be able to build and refine AI-generated outputs. The ad also looks for candidates interested in using AI to improve engineering practices.
Where do I apply?
On the official Datadog posting, through the job link on this page.
What happens when I tailor my resume here?
Your resume opens in the editor next to this job. Tailor it in one click, then keep or discard the edits. You only need an account to download.