Your Lambda resume, matched to the job ad
Drop in your resume and it opens next to this job, ready to tailor in one click.
4.8 from 167 in-app reviews
Senior Software Engineer - Compute
Lambda · San Francisco Office (Fremont St) · San Jose Office (First St) · Bellevue Office
Tailor your resume to this job
No account needed to start.
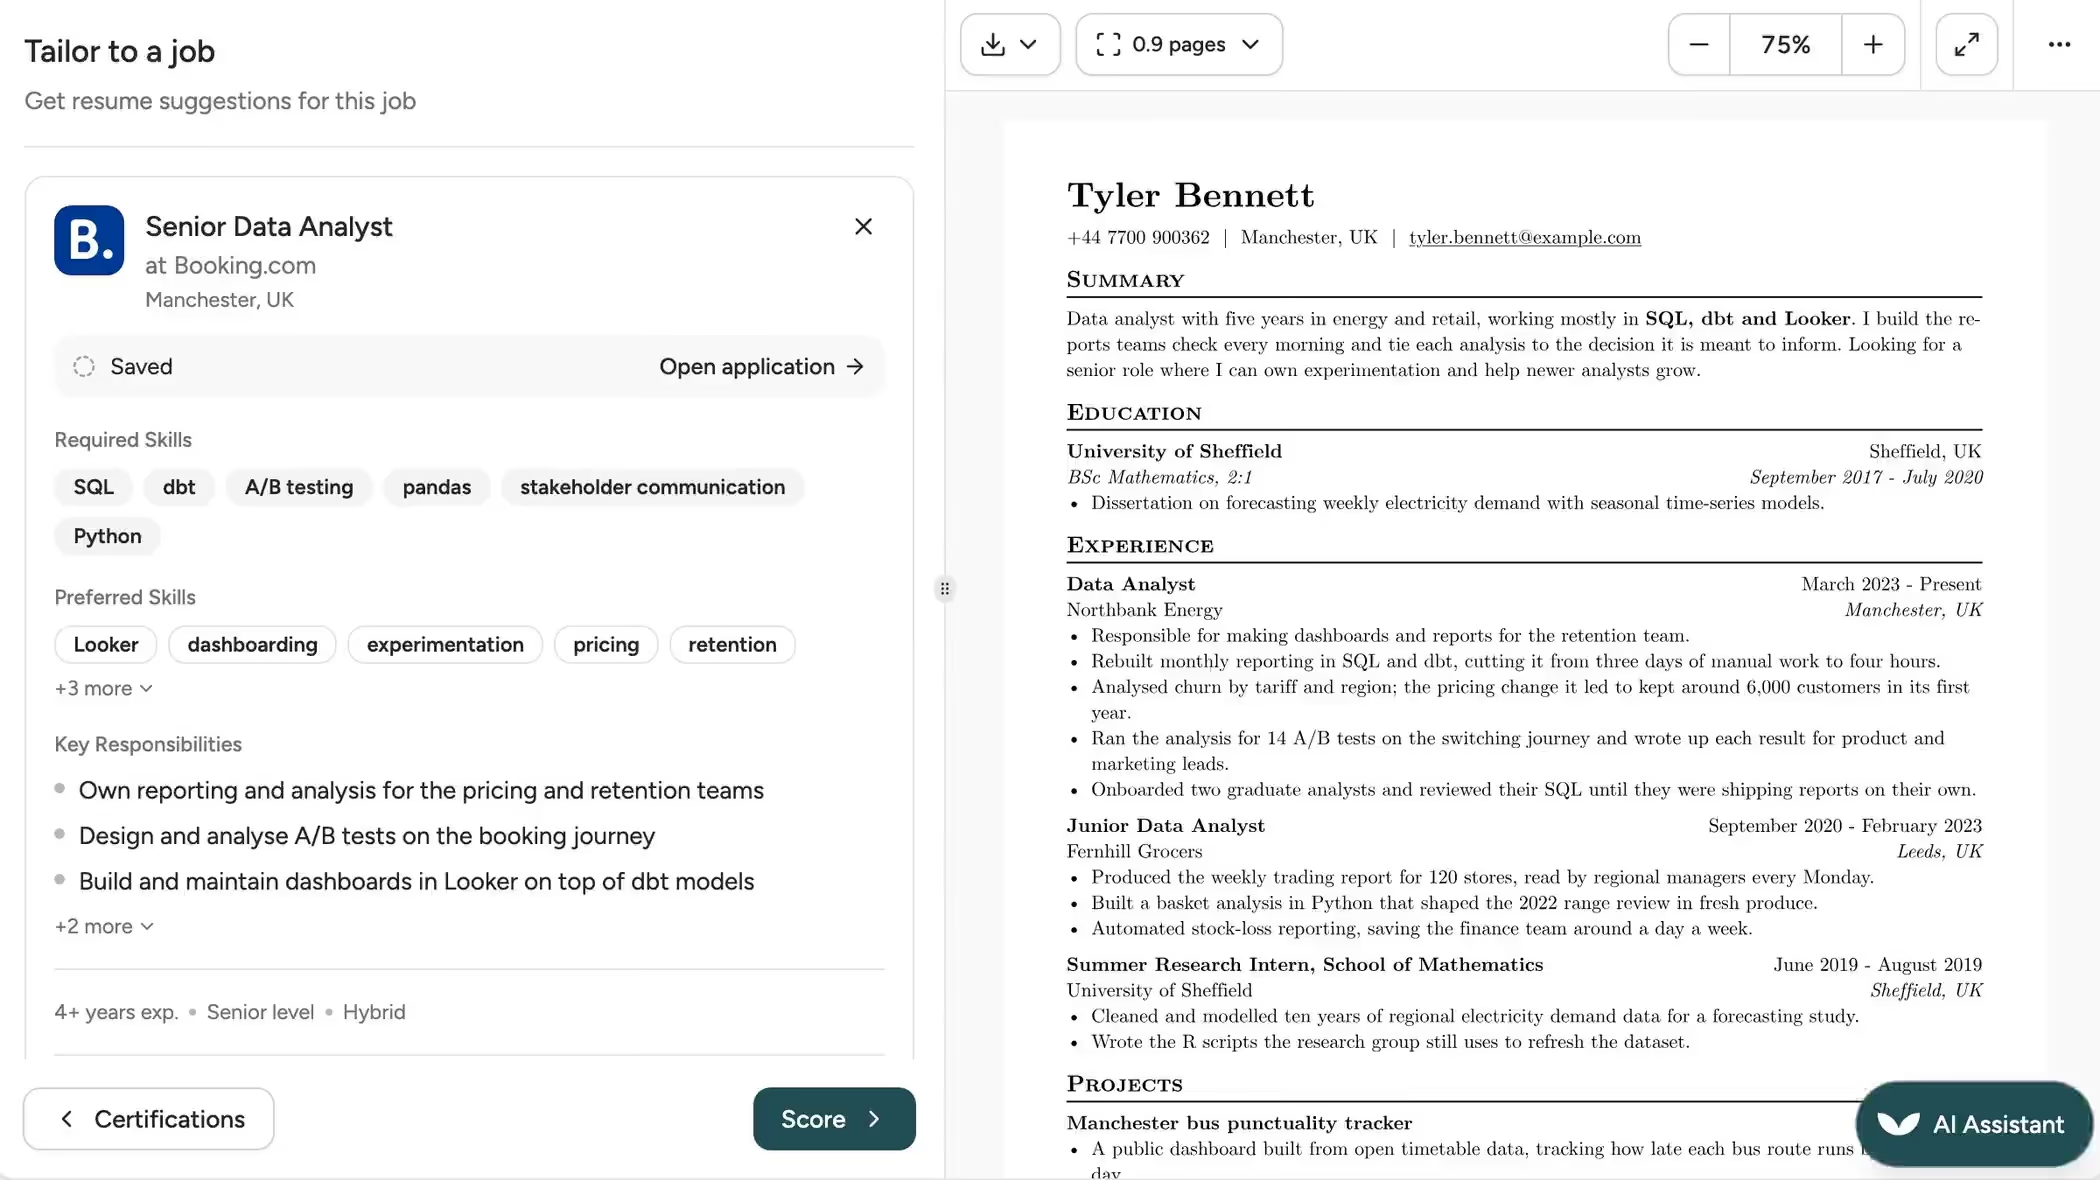
What Lambda asks for
From Lambda's Senior Software Engineer - Compute ad, checked 3 Nov 2026.
Go or Python in production
At least 5 years of experience using Go or Python to build and maintain software in live production environments.
Bare metal and virtualization
At least 5 years of experience managing and configuring hardware for bare metal and virtual machines.
Linux and network debugging
Technical comfort in Linux environments, including the ability to find and fix problems at the operating system, hardware, and networking layers.
Distributed systems and orchestration
Building and maintaining distributed systems to manage and organize compute resources across different hardware types.
GPU and high performance computing
Familiarity with GPU-based infrastructure or environments built for high performance computing and AI workloads.
The ad asks for 5 or more years of experience with Go or Python, plus 5 or more years with bare metal and virtualization hardware. Presence in the San Francisco, San Jose, or Bellevue office is required 4 days per week.
How the example answers the ad
Four of the five requirements above, each matched to a line in the example.
GPU and high performance computing
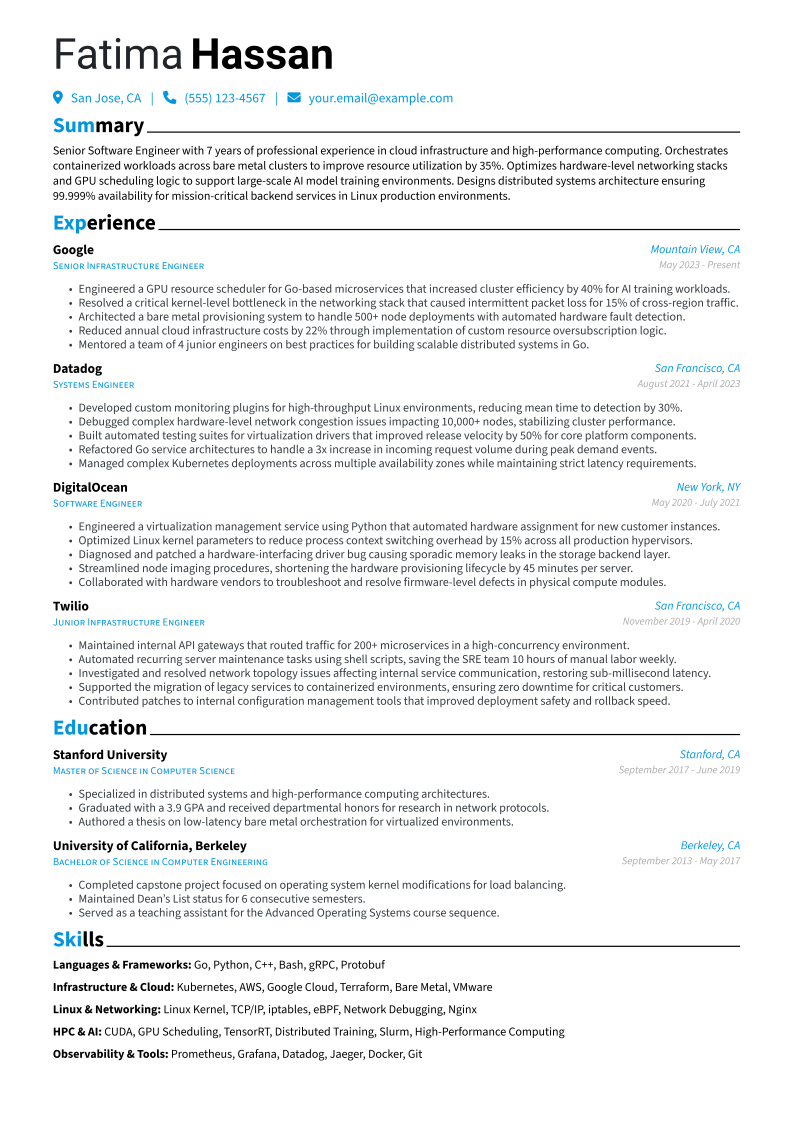
“Engineered a GPU resource scheduler for Go-based microservices that increased cluster efficiency by 40% for AI training workloads.”
Constructing a scheduler for GPU resources specifically for AI training tasks shows familiarity with high performance computing infrastructure.
Go or Python in production
“Engineered a virtualization management service using Python that automated hardware assignment for new customer instances.”
Building a virtualization service using Python shows the use of this language in a live production environment.
Bare metal and virtualization
“Architected a bare metal provisioning system to handle 500+ node deployments with automated hardware fault detection.”
Developing a provisioning system for 500 nodes shows experience managing and configuring hardware for bare metal deployments.
Linux and network debugging
“Debugged complex hardware-level network congestion issues impacting 10,000+ nodes, stabilizing cluster performance.”
Troubleshooting network congestion at the hardware level across 10,000 nodes shows technical comfort fixing problems at the networking and hardware layers.
The whole example as text
Fatima Hassan · Senior Infrastructure Engineer
Summary
Senior Software Engineer with 7 years of professional experience in cloud infrastructure and high-performance computing. Orchestrates containerized workloads across bare metal clusters to improve resource utilization by 35%. Optimizes hardware-level networking stacks and GPU scheduling logic to support large-scale AI model training environments. Designs distributed systems architecture ensuring 99.999% availability for mission-critical backend services in Linux production environments.
Experience
Senior Infrastructure Engineer · Google
Mountain View, CA · 2023 - Present
- Engineered a GPU resource scheduler for Go-based microservices that increased cluster efficiency by 40% for AI training workloads.
- Resolved a critical kernel-level bottleneck in the networking stack that caused intermittent packet loss for 15% of cross-region traffic.
- Architected a bare metal provisioning system to handle 500+ node deployments with automated hardware fault detection.
- Reduced annual cloud infrastructure costs by 22% through implementation of custom resource oversubscription logic.
- Mentored a team of 4 junior engineers on best practices for building scalable distributed systems in Go.
Systems Engineer · Datadog
San Francisco, CA · 2021 - 2023
- Developed custom monitoring plugins for high-throughput Linux environments, reducing mean time to detection by 30%.
- Debugged complex hardware-level network congestion issues impacting 10,000+ nodes, stabilizing cluster performance.
- Built automated testing suites for virtualization drivers that improved release velocity by 50% for core platform components.
- Refactored Go service architectures to handle a 3x increase in incoming request volume during peak demand events.
- Managed complex Kubernetes deployments across multiple availability zones while maintaining strict latency requirements.
Software Engineer · DigitalOcean
New York, NY · 2020 - 2021
- Engineered a virtualization management service using Python that automated hardware assignment for new customer instances.
- Optimized Linux kernel parameters to reduce process context switching overhead by 15% across all production hypervisors.
- Diagnosed and patched a hardware-interfacing driver bug causing sporadic memory leaks in the storage backend layer.
- Streamlined node imaging procedures, shortening the hardware provisioning lifecycle by 45 minutes per server.
- Collaborated with hardware vendors to troubleshoot and resolve firmware-level defects in physical compute modules.
Junior Infrastructure Engineer · Twilio
San Francisco, CA · 2019 - 2020
- Maintained internal API gateways that routed traffic for 200+ microservices in a high-concurrency environment.
- Automated recurring server maintenance tasks using shell scripts, saving the SRE team 10 hours of manual labor weekly.
- Investigated and resolved network topology issues affecting internal service communication, restoring sub-millisecond latency.
- Supported the migration of legacy services to containerized environments, ensuring zero downtime for critical customers.
- Contributed patches to internal configuration management tools that improved deployment safety and rollback speed.
Education
Master of Science in Computer Science · Stanford University
Stanford, CA · 2017 - 2019
- Specialized in distributed systems and high-performance computing architectures.
- Graduated with a 3.9 GPA and received departmental honors for research in network protocols.
- Authored a thesis on low-latency bare metal orchestration for virtualized environments.
Bachelor of Science in Computer Engineering · University of California, Berkeley
Berkeley, CA · 2013 - 2017
- Completed capstone project focused on operating system kernel modifications for load balancing.
- Maintained Dean's List status for 6 consecutive semesters.
- Served as a teaching assistant for the Advanced Operating Systems course sequence.
Skills
More Lambda roles like this one
- Senior Software Engineer - Core Cloud PlatformSan Francisco Office (Fremont St) · San Jose Office (First St) · Bellevue Office
- Senior Software Engineer - Fleet EngineeringSan Francisco Office (Fremont St) · San Jose Office (Zanker) · Bellevue Office
- Senior Software Engineer - Infrastructure StorageSan Francisco Office (Fremont St) · San Jose Office (First St) · Bellevue Office
Frequently asked questions
Is the example from an employee?
No. It is an AI-written example for this ad, made to show how a resume can answer it.
Is this a remote role?
No. The ad requires you to be in the San Francisco, San Jose, or Bellevue office 4 days per week. Currently, Tuesday is the designated work from home day.
Do I need experience with specific cloud internals?
It is preferred but not required. The ad lists experience with core public cloud internals like KVM, QEMU, and fleet health as nice to have.
Where do I apply?
On the official Lambda posting, through the job link on this page.
What happens when I tailor my resume here?
Your resume opens in the editor next to this job. Tailor it in one click, then keep or discard the edits. You only need an account to download.