Your Modal resume, matched to the job ad
Drop in your resume and it opens next to this job, ready to tailor in one click.
4.8 from 167 in-app reviews
Member of Technical Staff - Systems
Modal · New York · San Francisco
Tailor your resume to this job
No account needed to start.
What Modal asks for
From Modal's Member of Technical Staff - Systems ad, checked 4 Nov 2026.
Distributed systems at scale
Building high-performance distributed systems for large-scale environments, with a focus on durability and reliability through complex production challenges.
Operating system foundations
Deep understanding of low-level systems including file systems, containers, and the Linux kernel.
Performance engineering
Experience optimizing systems to reduce latency, specifically finding ways to shave milliseconds off execution times.
Rust programming
Prior experience using the Rust programming language for systems engineering.
Incident response and on-call
Participating in on-call rotations and managing the response to production incidents.
The ad asks for 5 or more years of experience writing production code and the ability to work in person in New York City or San Francisco.
How the example answers the ad
Four of the five requirements above, each matched to a line in the example.
Rust programming
“Developed a Rust-based micro-service for container resource allocation, improving CPU utilization efficiency by 18 percent.”
Building a micro-service for container resource allocation shows practical application of Rust programming in a systems engineering context.
Operating system foundations
“Implemented custom file system optimization strategies in Linux that lowered disk I/O wait times by 12 percent.”
Developing optimization strategies for Linux file systems shows the depth of understanding required for operating system foundations.
Performance engineering
“Analyzed cold-start latency in serverless function clusters and implemented code-level caching to decrease execution start times by 60 milliseconds.”
Decreasing execution start times by 60 milliseconds through caching in serverless clusters shows performance engineering focused on millisecond-level latency reduction.
Incident response and on-call
“Led incident response rotations for a fleet of 50,000 servers, reducing mean time to recovery by 30 percent through automated health checks.”
Leading rotations for 50,000 servers and reducing recovery time through automation shows experience in incident response and on-call management.
The whole example as text
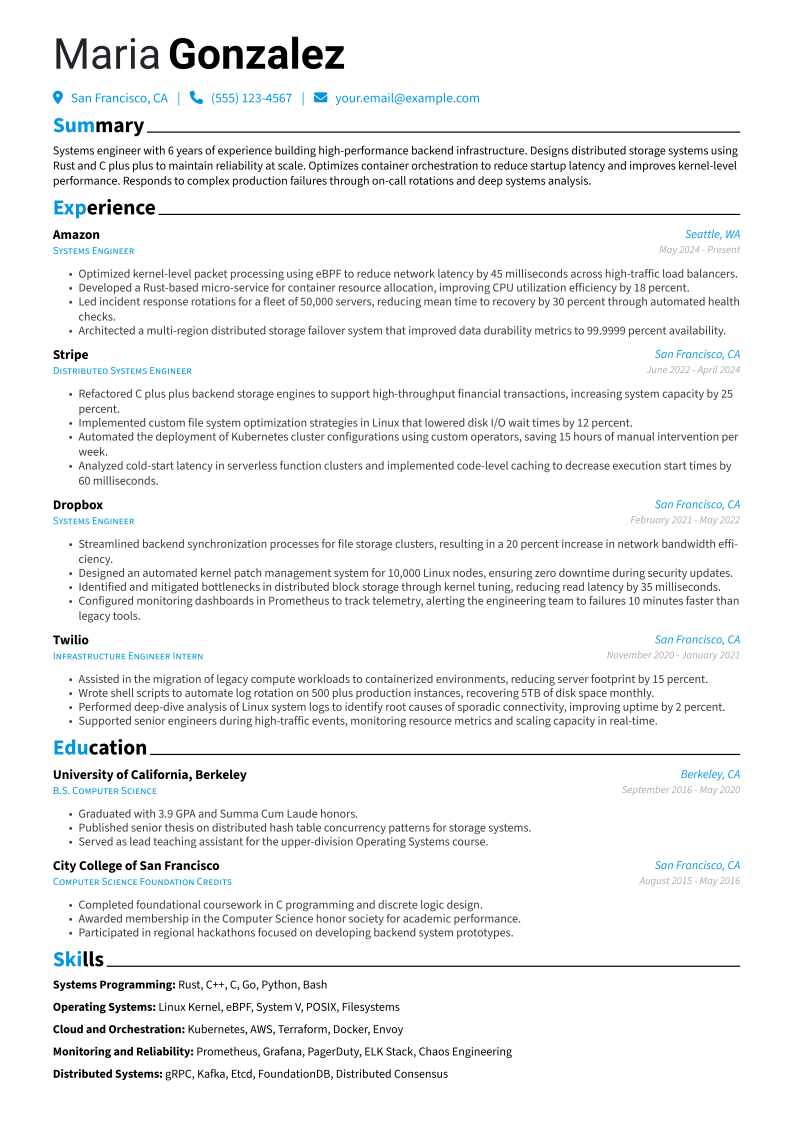
Maria Gonzalez · Systems Engineer
Summary
Systems engineer with 6 years of experience building high-performance backend infrastructure. Designs distributed storage systems using Rust and C plus plus to maintain reliability at scale. Optimizes container orchestration to reduce startup latency and improves kernel-level performance. Responds to complex production failures through on-call rotations and deep systems analysis.
Experience
Systems Engineer · Amazon
Seattle, WA · 2024 - Present
- Optimized kernel-level packet processing using eBPF to reduce network latency by 45 milliseconds across high-traffic load balancers.
- Developed a Rust-based micro-service for container resource allocation, improving CPU utilization efficiency by 18 percent.
- Led incident response rotations for a fleet of 50,000 servers, reducing mean time to recovery by 30 percent through automated health checks.
- Architected a multi-region distributed storage failover system that improved data durability metrics to 99.9999 percent availability.
Distributed Systems Engineer · Stripe
San Francisco, CA · 2022 - 2024
- Refactored C plus plus backend storage engines to support high-throughput financial transactions, increasing system capacity by 25 percent.
- Implemented custom file system optimization strategies in Linux that lowered disk I/O wait times by 12 percent.
- Automated the deployment of Kubernetes cluster configurations using custom operators, saving 15 hours of manual intervention per week.
- Analyzed cold-start latency in serverless function clusters and implemented code-level caching to decrease execution start times by 60 milliseconds.
Systems Engineer · Dropbox
San Francisco, CA · 2021 - 2022
- Streamlined backend synchronization processes for file storage clusters, resulting in a 20 percent increase in network bandwidth efficiency.
- Designed an automated kernel patch management system for 10,000 Linux nodes, ensuring zero downtime during security updates.
- Identified and mitigated bottlenecks in distributed block storage through kernel tuning, reducing read latency by 35 milliseconds.
- Configured monitoring dashboards in Prometheus to track telemetry, alerting the engineering team to failures 10 minutes faster than legacy tools.
Infrastructure Engineer Intern · Twilio
San Francisco, CA · 2020 - 2021
- Assisted in the migration of legacy compute workloads to containerized environments, reducing server footprint by 15 percent.
- Wrote shell scripts to automate log rotation on 500 plus production instances, recovering 5TB of disk space monthly.
- Performed deep-dive analysis of Linux system logs to identify root causes of sporadic connectivity, improving uptime by 2 percent.
- Supported senior engineers during high-traffic events, monitoring resource metrics and scaling capacity in real-time.
Education
B.S. Computer Science · University of California, Berkeley
Berkeley, CA · 2016 - 2020
- Graduated with 3.9 GPA and Summa Cum Laude honors.
- Published senior thesis on distributed hash table concurrency patterns for storage systems.
- Served as lead teaching assistant for the upper-division Operating Systems course.
Computer Science Foundation Credits · City College of San Francisco
San Francisco, CA · 2015 - 2016
- Completed foundational coursework in C programming and discrete logic design.
- Awarded membership in the Computer Science honor society for academic performance.
- Participated in regional hackathons focused on developing backend system prototypes.
Skills
Frequently asked questions
Is the example from an employee?
No. It is an AI-written example for this ad, made to show how a resume can answer it.
Is this role remote?
No. The ad states that you must be able to work in person in the New York City or San Francisco office.
What level of experience is required?
The ad asks for 5 or more years of experience writing high-quality production code.
Where do I apply?
On the official Modal posting, through the job link on this page.
What happens when I tailor my resume here?
Your resume opens in the editor next to this job. Tailor it in one click, then keep or discard the edits. You only need an account to download.