Your Robinhood resume, matched to the job ad
Drop in your resume and it opens next to this job, ready to tailor in one click.
4.8 from 167 in-app reviews
Senior Software Engineer, AI Infra
Robinhood · Menlo Park, CA
Tailor your resume to this job
No account needed to start.
What Robinhood asks for
From Robinhood's Senior Software Engineer, AI Infra ad, checked 2 Nov 2026.
Distributed systems and infrastructure
Building and operating large-scale distributed systems in production, with a focus on system performance, reliability, and scalability.
Production system optimization
Taking ownership of complex technical problems to improve resource utilization and reduce latency in production environments.
AI and ML infrastructure
Designing and scaling the foundations for machine learning, including feature stores, training pipelines, model serving, and observability.
GPU and LLM gateways
Experience with specialized AI infrastructure such as LLM gateways, intelligent routing, or scheduling workloads for GPUs.
This role is based in the Menlo Park office. Robinhood expects in-person attendance at least 3 days per week.
How the example answers the ad
Three of the four requirements above, each matched to a line in the example.
GPU and LLM gateways
“Designed and deployed a multi-region LLM inference gateway, serving 500k requests per day with sub-100ms P99 latency.”
Deploying a multi-region gateway that handles 500,000 daily requests for LLM inference shows experience with intelligent routing and specialized AI infrastructure.
AI and ML infrastructure
“Orchestrated 200+ A100 GPU nodes for real-time fraud detection model training, reducing pipeline completion time by 30 percent.”
Managing 200 A100 nodes for real-time model training shows the ability to scale foundations for machine learning pipelines.
Production system optimization
“Scaled backend API services handling 50k transactions per minute, reducing overall server CPU utilization by 15 percent through code optimization.”
Optimizing code to reduce CPU use by 15 percent while handling 50,000 transactions per minute shows ownership of resource utilization in production.
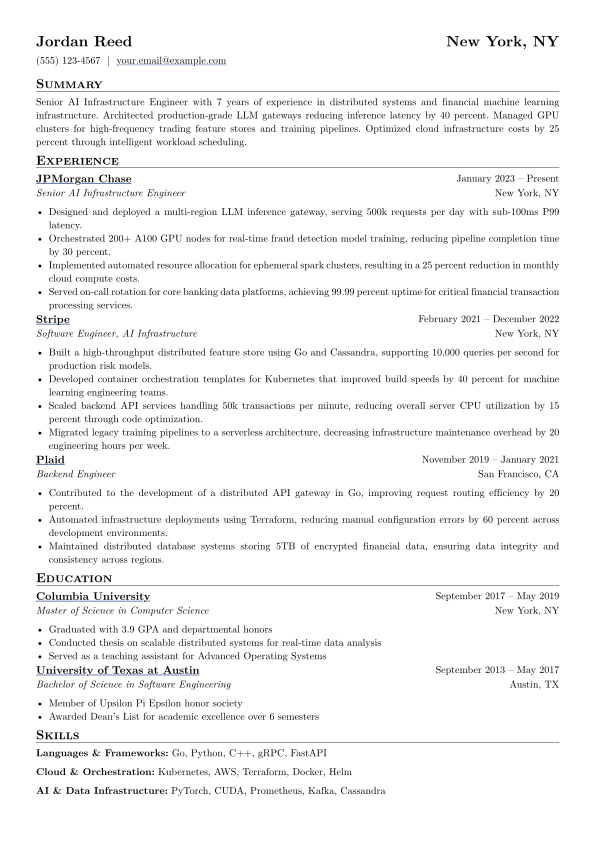
The whole example as text
Jordan Reed · Senior AI Infrastructure Engineer
Summary
Senior AI Infrastructure Engineer with 7 years of experience in distributed systems and financial machine learning infrastructure. Architected production-grade LLM gateways reducing inference latency by 40 percent. Managed GPU clusters for high-frequency trading feature stores and training pipelines. Optimized cloud infrastructure costs by 25 percent through intelligent workload scheduling.
Experience
Senior AI Infrastructure Engineer · JPMorgan Chase
New York, NY · 2023 - Present
- Designed and deployed a multi-region LLM inference gateway, serving 500k requests per day with sub-100ms P99 latency.
- Orchestrated 200+ A100 GPU nodes for real-time fraud detection model training, reducing pipeline completion time by 30 percent.
- Implemented automated resource allocation for ephemeral spark clusters, resulting in a 25 percent reduction in monthly cloud compute costs.
- Served on-call rotation for core banking data platforms, achieving 99.99 percent uptime for critical financial transaction processing services.
Software Engineer, AI Infrastructure · Stripe
New York, NY · 2021 - 2022
- Built a high-throughput distributed feature store using Go and Cassandra, supporting 10,000 queries per second for production risk models.
- Developed container orchestration templates for Kubernetes that improved build speeds by 40 percent for machine learning engineering teams.
- Scaled backend API services handling 50k transactions per minute, reducing overall server CPU utilization by 15 percent through code optimization.
- Migrated legacy training pipelines to a serverless architecture, decreasing infrastructure maintenance overhead by 20 engineering hours per week.
Backend Engineer · Plaid
San Francisco, CA · 2019 - 2021
- Contributed to the development of a distributed API gateway in Go, improving request routing efficiency by 20 percent.
- Automated infrastructure deployments using Terraform, reducing manual configuration errors by 60 percent across development environments.
- Maintained distributed database systems storing 5TB of encrypted financial data, ensuring data integrity and consistency across regions.
Education
Master of Science in Computer Science · Columbia University
New York, NY · 2017 - 2019
- Graduated with 3.9 GPA and departmental honors
- Conducted thesis on scalable distributed systems for real-time data analysis
- Served as a teaching assistant for Advanced Operating Systems
Bachelor of Science in Software Engineering · University of Texas at Austin
Austin, TX · 2013 - 2017
- Member of Upsilon Pi Epsilon honor society
- Awarded Dean's List for academic excellence over 6 semesters
Skills
Frequently asked questions
Is the example from an employee?
No. It is an AI-written example for this ad, made to show how a resume can answer it.
Is this role remote?
No. The role is based in the Menlo Park office, and the company expects employees to attend in person at least 3 days per week.
Do I need to be an expert in machine learning already?
The ad asks for an interest in the field and a willingness to learn, though prior experience with ML infrastructure or GPU scheduling is considered a bonus.
Where do I apply?
On the official Robinhood posting, through the job link on this page.
What happens when I tailor my resume here?
Your resume opens in the editor next to this job. Tailor it in one click, then keep or discard the edits. You only need an account to download.