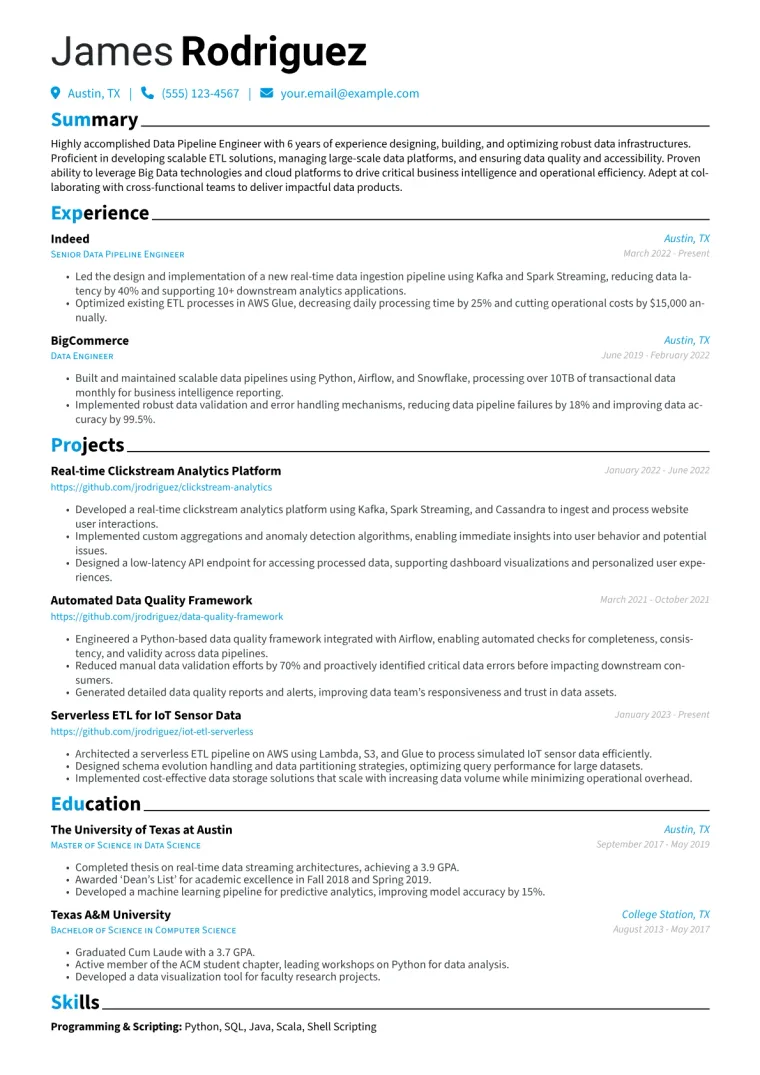
At Indeed, I spearheaded a crucial initiative to re-architect our core log ingestion pipeline, successfully reducing processing latency by 45% for over 50TB of daily data. This project involved migrating from a legacy Hadoop MapReduce system to a high-throughput Apache Kafka and Apache Spark Streaming architecture, significantly improving the real-time availability and freshness of critical analytics for internal stakeholders. The complexity required meticulous planning to ensure zero data loss during the transition, despite continuous, high-volume data streams.
My experience at Indeed includes developing robust Python ETL scripts leveraging Apache Spark to process multi-source financial transaction data, achieving 99.9% data accuracy and reducing data discrepancy resolution time by 20%. I also engineered a real-time user behavior analytics platform utilizing Kafka and Scala, supporting over 10,000 events/second while maintaining sub-second latency for dashboard updates. Furthermore, I optimized complex SQL queries across our PostgreSQL and Redshift data warehouses, which improved report generation times by an average of 30% for key business intelligence dashboards, directly impacting leadership decision-making.
My expertise in architecting high-throughput, fault-tolerant data systems aligns perfectly with Veridian Data Solutions' mission to deliver cutting-edge real-time data platforms. I am particularly drawn to your recent advancements in predictive analytics, specifically Project 'Aurora,' which leverages advanced Kafka streams for real-time insights. My extensive experience with Scala and Apache Spark on high-volume, mission-critical data would enable me to immediately contribute to enhancing your data ingestion and processing capabilities, ensuring robust and scalable solutions.
My background in optimizing complex data ecosystems and delivering robust, scalable solutions directly prepares me to contribute significantly to Veridian Data Solutions' continued innovation. I am confident that my practical experience with modern data technologies such as Kafka, Spark, and Scala can have a substantial impact on your team's objectives. I look forward to discussing how my skills and experience can support Veridian's vision for data excellence during an interview.
Best regards,
James Rodriguez