Data Pipeline Engineer Resume Example
 Example by JobSprout
Free to use. No download fee.
Market Insights
Data Pipeline Engineer
Salary Range
Salary Trend
Mar 2025 – Feb 2026
12-Month Trend
Based on advertised Software Engineering roles.
US market data · Source: Adzuna · Updated Mar 2026
How useful was this template?
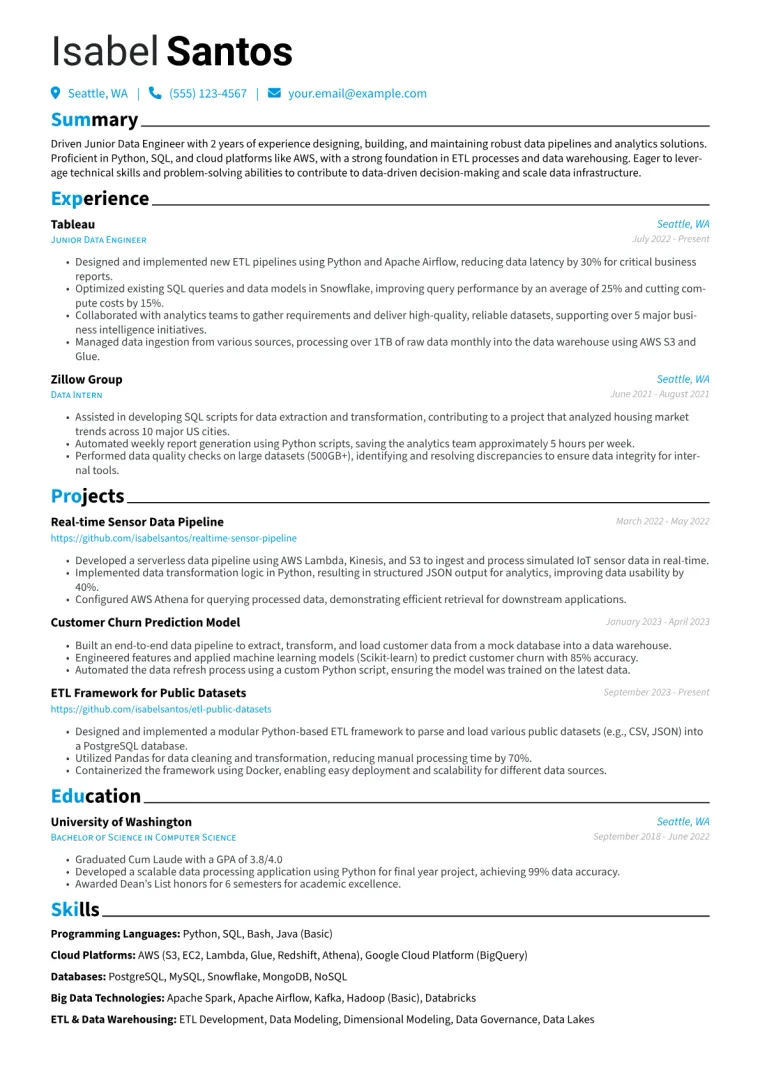
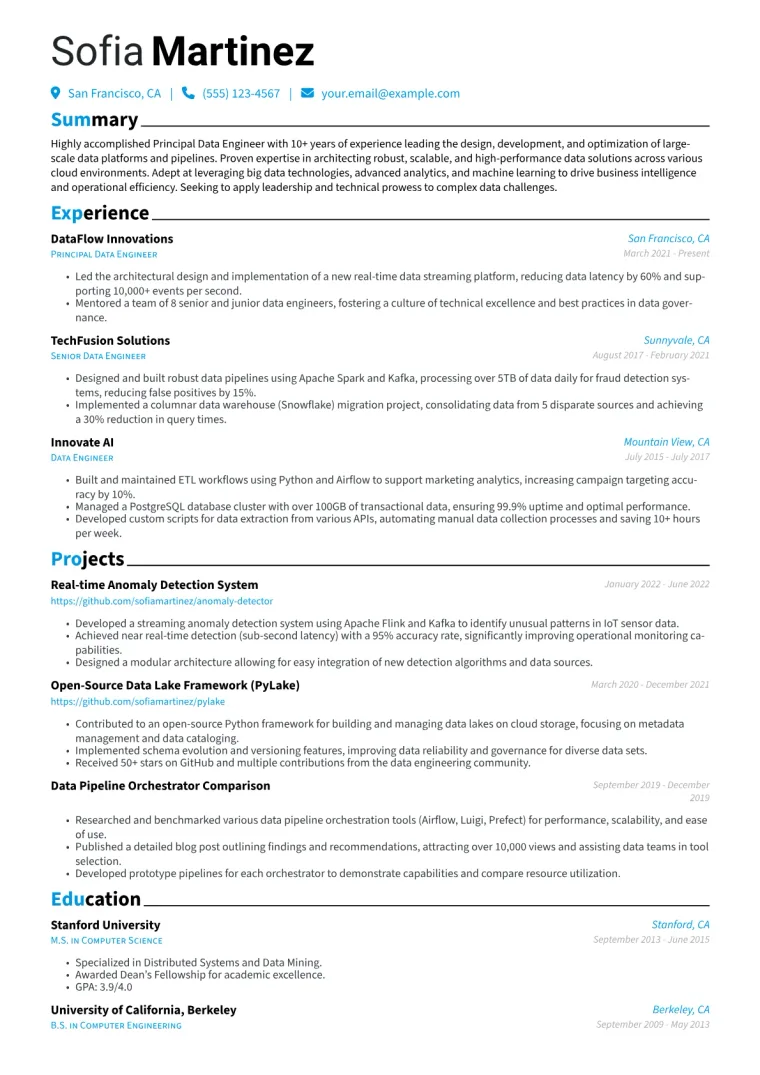
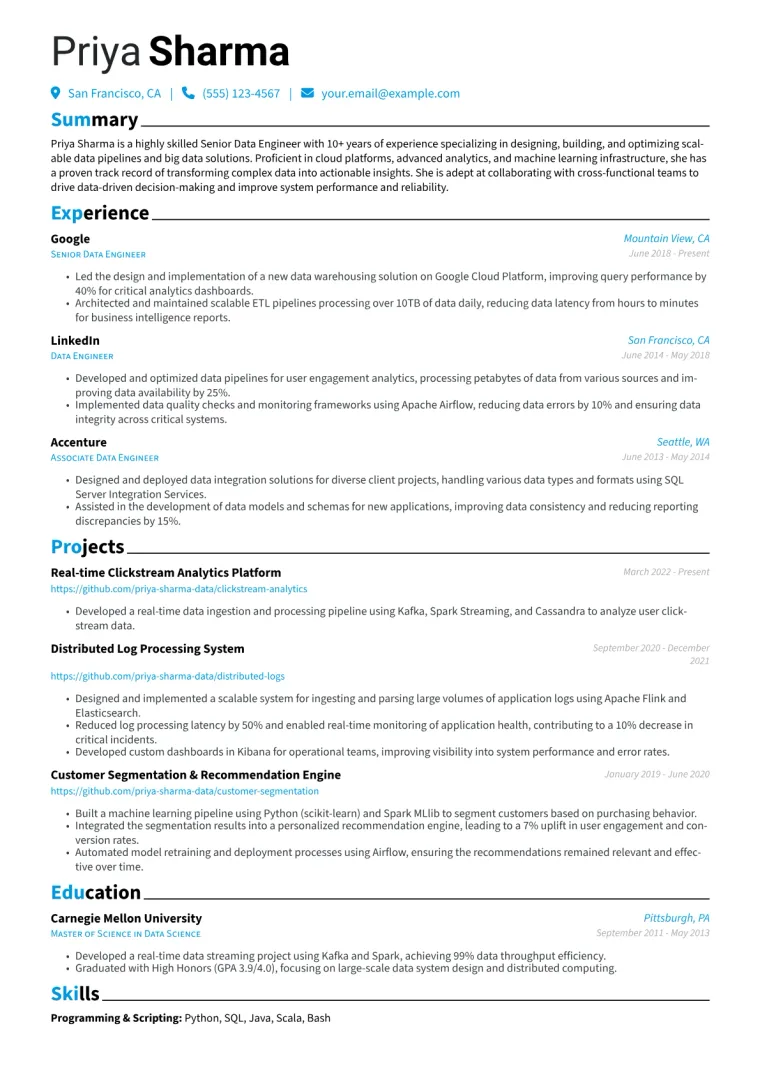
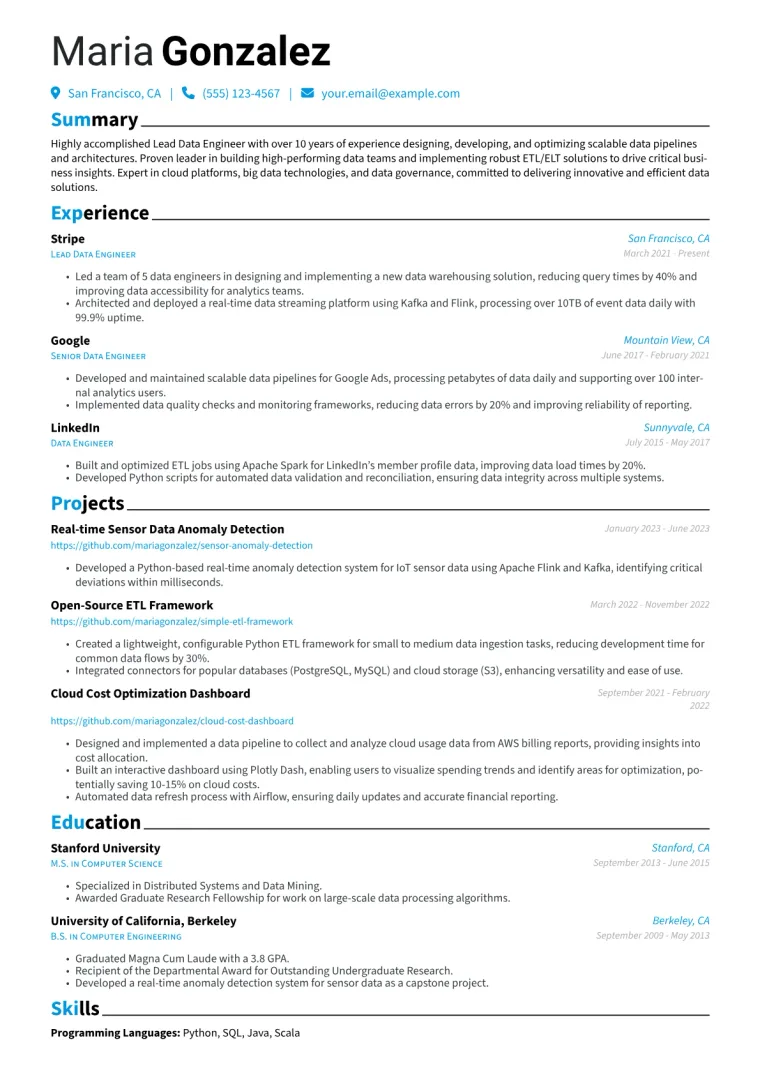
Data Pipeline Engineer resume samples
Three complete resumes, each in a different design.
Free to use. No download fee.
What makes a strong Data Pipeline Engineer resume?
US median salary $160,720 ·
Hiring managers seek Data Pipeline Engineers who demonstrate clear impact on data infrastructure and quality. Key achievements involve reducing data processing latency, managing petabyte-scale data ingestion, and implementing robust ETL/ELT solutions. Employers look for expertise in orchestration tools like Apache Airflow, real-time streaming platforms such as Kafka, and distributed processing frameworks like Spark or Flink. Experience with major cloud data services on AWS, GCP, or Azure, alongside strong SQL and Python proficiency, signals readiness for complex data challenges. Certifications like AWS Certified Data Analytics also stand out, showing dedicated commitment to modern data practices.
Why this example works
This example resume effectively showcases these critical elements. Achievements are quantified, for instance, detailing how a candidate “Optimized Spark jobs, decreasing runtime by 40% and reducing cloud costs by 20%.” Skills are thoughtfully grouped into categories like “Data Orchestration,” “Cloud Platforms,” and “Programming Languages,” making technical breadth immediately apparent. Specific tools such as Airflow, Kafka, and Snowflake are highlighted, demonstrating practical application. The structure ensures hiring managers can quickly grasp the candidate's deep technical capabilities and successful project contributions in data engineering.
Data Pipeline Engineer resume example (text version)
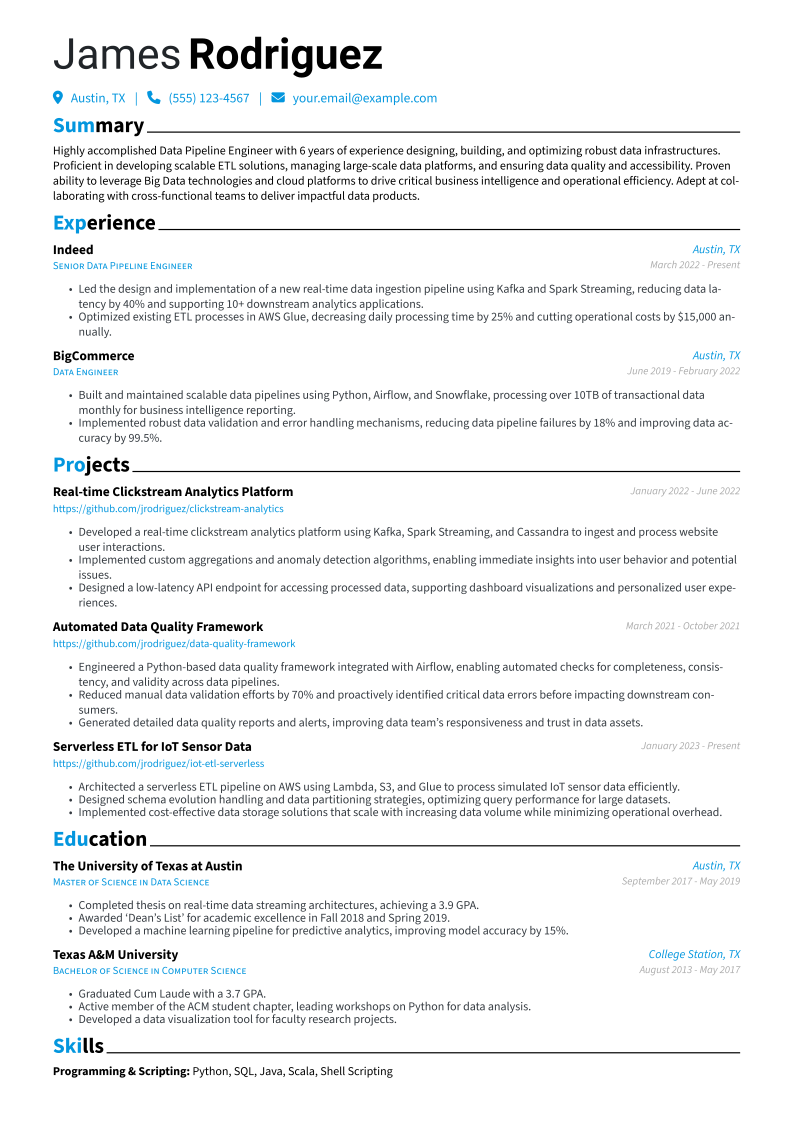
James Rodriguez · Data Pipeline Engineer
Summary
Highly accomplished Data Pipeline Engineer with 6 years of experience designing, building, and optimizing robust data infrastructures. Proficient in developing scalable ETL solutions, managing large-scale data platforms, and ensuring data quality and accessibility. Proven ability to leverage Big Data technologies and cloud platforms to drive critical business intelligence and operational efficiency. Adept at collaborating with cross-functional teams to deliver impactful data products.
Experience
Senior Data Pipeline Engineer · Indeed
Austin, TX · 2022 - Present
- Led the design and implementation of a new real-time data ingestion pipeline using Kafka and Spark Streaming, reducing data latency by 40% and supporting 10+ downstream analytics applications.
- Optimized existing ETL processes in AWS Glue, decreasing daily processing time by 25% and cutting operational costs by $15,000 annually.
- Mentored a team of 3 junior data engineers, improving code quality and deployment efficiency by 30% through best practices and code reviews.
- Developed and maintained data quality monitoring dashboards using Grafana and Prometheus, proactively identifying and resolving data anomalies for over 5TB of daily data.
Data Engineer · BigCommerce
Austin, TX · 2019 - 2022
- Built and maintained scalable data pipelines using Python, Airflow, and Snowflake, processing over 10TB of transactional data monthly for business intelligence reporting.
- Implemented robust data validation and error handling mechanisms, reducing data pipeline failures by 18% and improving data accuracy by 99.5%.
- Collaborated with product and analytics teams to gather requirements and deliver data solutions, resulting in a 10% increase in critical metric visibility.
- Automated deployment of data assets using CI/CD pipelines, accelerating delivery cycles by 20%.
Education
Master of Science in Data Science · The University of Texas at Austin
Austin, TX · 2017 - 2019
- Completed thesis on real-time data streaming architectures, achieving a 3.9 GPA.
- Awarded 'Dean's List' for academic excellence in Fall 2018 and Spring 2019.
- Developed a machine learning pipeline for predictive analytics, improving model accuracy by 15%.
Bachelor of Science in Computer Science · Texas A&M University
College Station, TX · 2013 - 2017
- Graduated Cum Laude with a 3.7 GPA.
- Active member of the ACM student chapter, leading workshops on Python for data analysis.
- Developed a data visualization tool for faculty research projects.
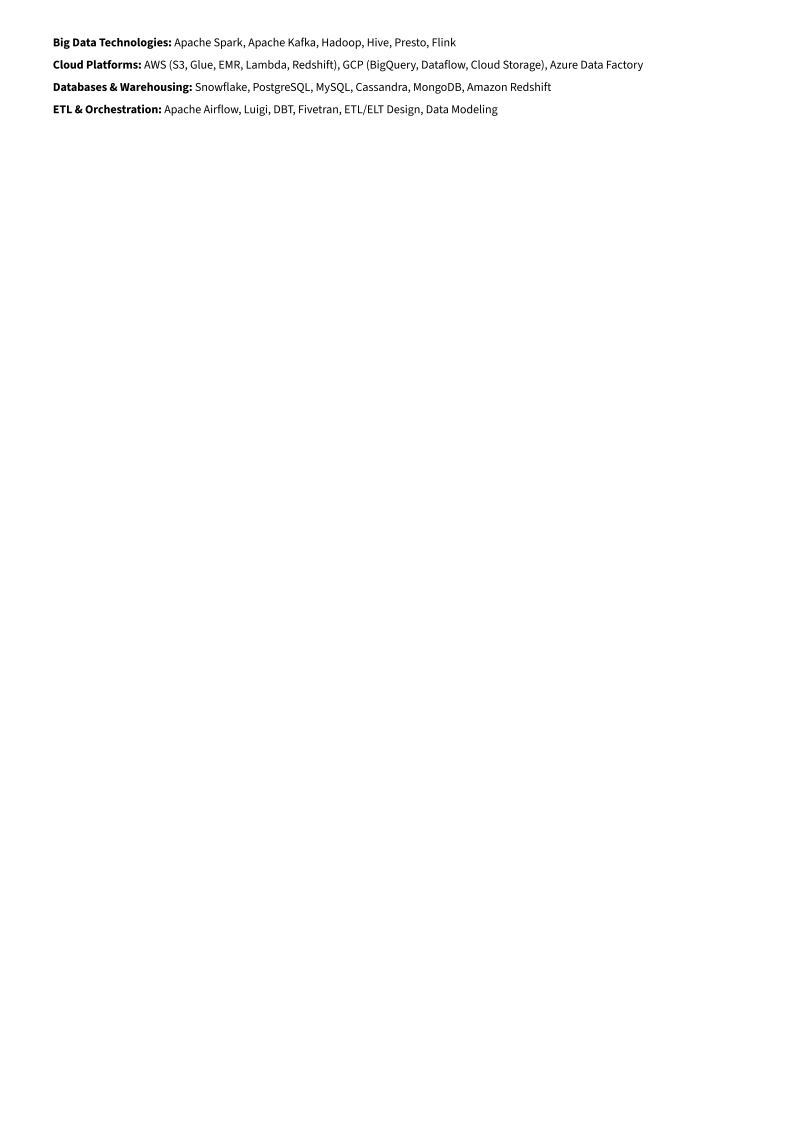
Skills
Data Pipeline Engineer resume example: Alternate Version
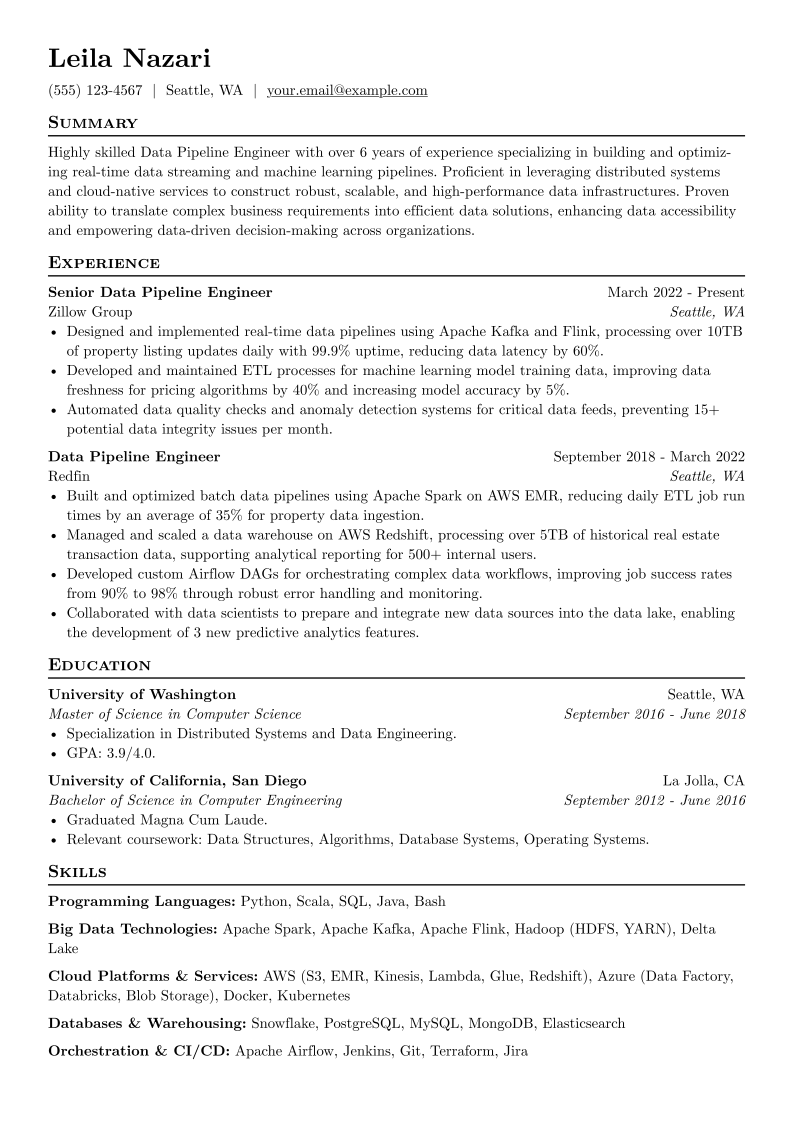
Leila Nazari · Data Pipeline Engineer
Summary
Highly skilled Data Pipeline Engineer with over 6 years of experience specializing in building and optimizing real-time data streaming and machine learning pipelines. Proficient in leveraging distributed systems and cloud-native services to construct robust, scalable, and high-performance data infrastructures. Proven ability to translate complex business requirements into efficient data solutions, enhancing data accessibility and empowering data-driven decision-making across organizations.
Experience
Senior Data Pipeline Engineer · Zillow Group
Seattle, WA · 2022 - Present
- Designed and implemented real-time data pipelines using Apache Kafka and Flink, processing over 10TB of property listing updates daily with 99.9% uptime, reducing data latency by 60%.
- Developed and maintained ETL processes for machine learning model training data, improving data freshness for pricing algorithms by 40% and increasing model accuracy by 5%.
- Automated data quality checks and anomaly detection systems for critical data feeds, preventing 15+ potential data integrity issues per month.
- Mentored junior engineers on best practices for scalable data pipeline development and cloud infrastructure management, contributing to a 25% improvement in team project delivery speed.
Data Pipeline Engineer · Redfin
Seattle, WA · 2018 - 2022
- Built and optimized batch data pipelines using Apache Spark on AWS EMR, reducing daily ETL job run times by an average of 35% for property data ingestion.
- Managed and scaled a data warehouse on AWS Redshift, processing over 5TB of historical real estate transaction data, supporting analytical reporting for 500+ internal users.
- Developed custom Airflow DAGs for orchestrating complex data workflows, improving job success rates from 90% to 98% through robust error handling and monitoring.
- Collaborated with data scientists to prepare and integrate new data sources into the data lake, enabling the development of 3 new predictive analytics features.
Education
Master of Science in Computer Science · University of Washington
Seattle, WA · 2016 - 2018
- Specialization in Distributed Systems and Data Engineering.
- GPA: 3.9/4.0.
Bachelor of Science in Computer Engineering · University of California, San Diego
La Jolla, CA · 2012 - 2016
- Graduated Magna Cum Laude.
- Relevant coursework: Data Structures, Algorithms, Database Systems, Operating Systems.
Skills
Data Pipeline Engineer resume example: Career Changer
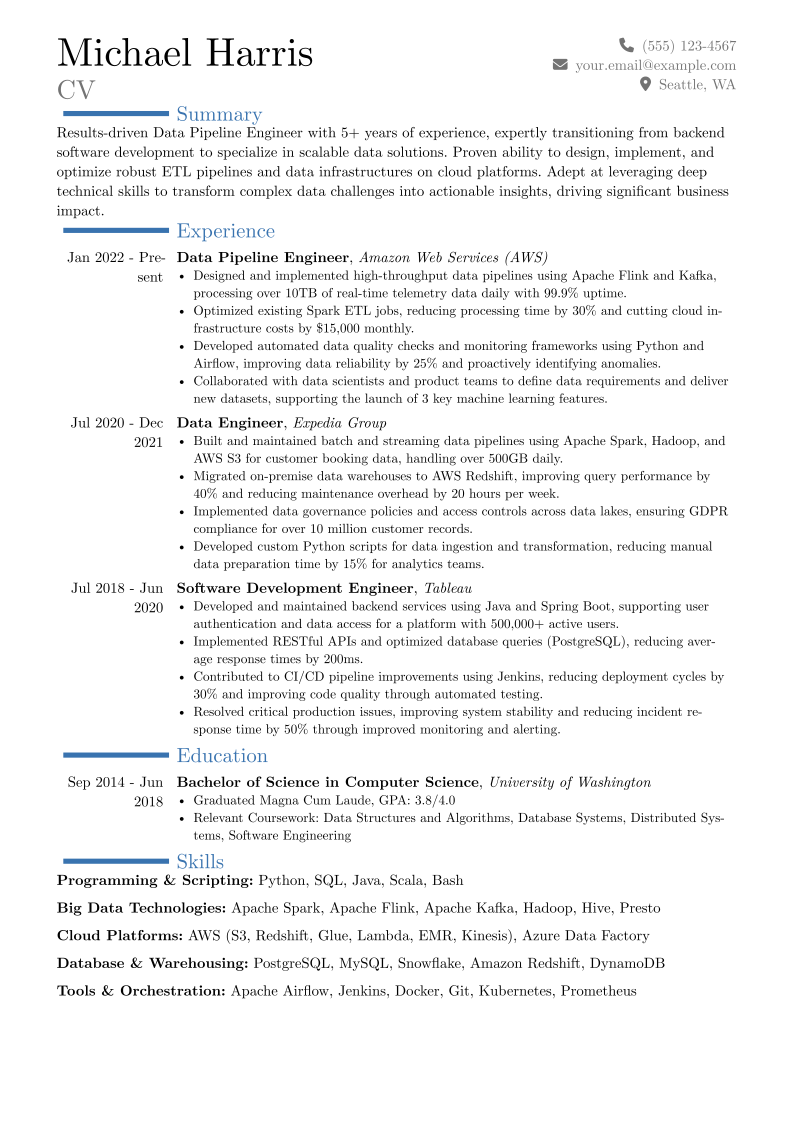
Michael Harris · Data Pipeline Engineer
Summary
Results-driven Data Pipeline Engineer with 5+ years of experience, expertly transitioning from backend software development to specialize in scalable data solutions. Proven ability to design, implement, and optimize robust ETL pipelines and data infrastructures on cloud platforms. Adept at leveraging deep technical skills to transform complex data challenges into actionable insights, driving significant business impact.
Experience
Data Pipeline Engineer · Amazon Web Services (AWS)
Seattle, WA · 2022 - Present
- Designed and implemented high-throughput data pipelines using Apache Flink and Kafka, processing over 10TB of real-time telemetry data daily with 99.9% uptime.
- Optimized existing Spark ETL jobs, reducing processing time by 30% and cutting cloud infrastructure costs by $15,000 monthly.
- Developed automated data quality checks and monitoring frameworks using Python and Airflow, improving data reliability by 25% and proactively identifying anomalies.
- Collaborated with data scientists and product teams to define data requirements and deliver new datasets, supporting the launch of 3 key machine learning features.
Data Engineer · Expedia Group
Seattle, WA · 2020 - 2021
- Built and maintained batch and streaming data pipelines using Apache Spark, Hadoop, and AWS S3 for customer booking data, handling over 500GB daily.
- Migrated on-premise data warehouses to AWS Redshift, improving query performance by 40% and reducing maintenance overhead by 20 hours per week.
- Implemented data governance policies and access controls across data lakes, ensuring GDPR compliance for over 10 million customer records.
- Developed custom Python scripts for data ingestion and transformation, reducing manual data preparation time by 15% for analytics teams.
Software Development Engineer · Tableau
Seattle, WA · 2018 - 2020
- Developed and maintained backend services using Java and Spring Boot, supporting user authentication and data access for a platform with 500,000+ active users.
- Implemented RESTful APIs and optimized database queries (PostgreSQL), reducing average response times by 200ms.
- Contributed to CI/CD pipeline improvements using Jenkins, reducing deployment cycles by 30% and improving code quality through automated testing.
- Resolved critical production issues, improving system stability and reducing incident response time by 50% through improved monitoring and alerting.
Education
Bachelor of Science in Computer Science · University of Washington
Seattle, WA · 2014 - 2018
- Graduated Magna Cum Laude, GPA: 3.8/4.0
- Relevant Coursework: Data Structures and Algorithms, Database Systems, Distributed Systems, Software Engineering
Skills
How useful was this template?
Example by JobSprout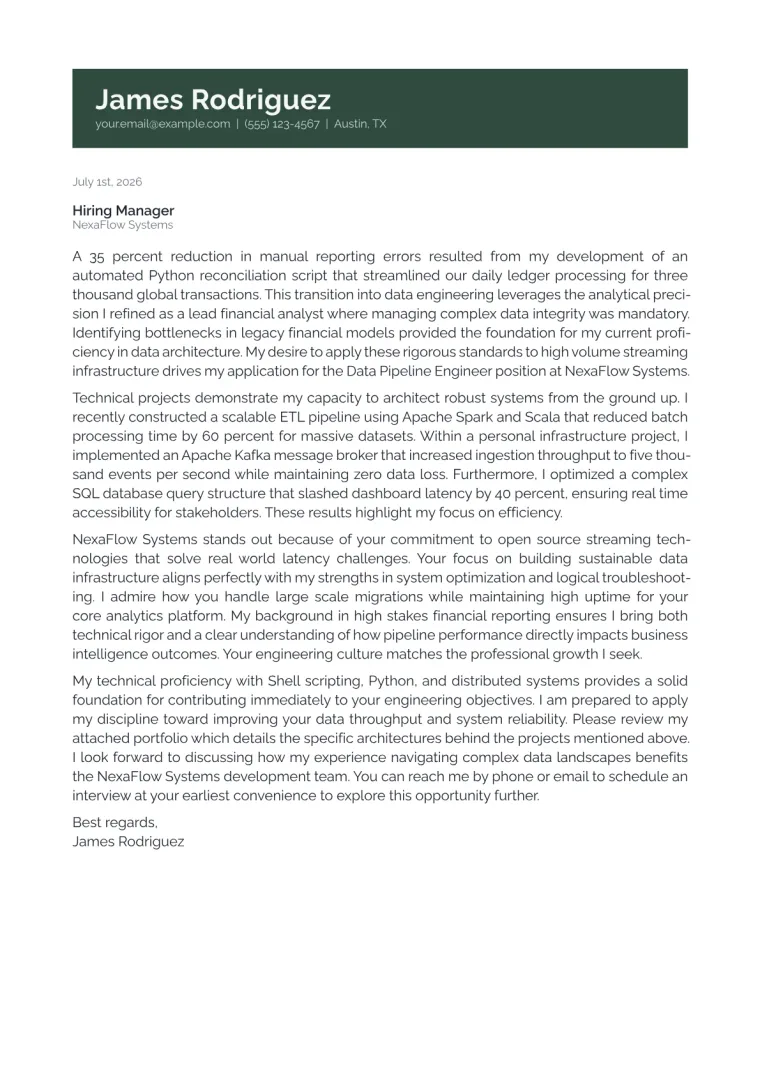
Data Pipeline Engineer cover letter for a career changer
Written for the same situation as this resume.
Data Pipeline Engineer resume summary example
Highly accomplished Data Pipeline Engineer with 6 years of experience designing, building, and optimizing robust data infrastructures. Proficient in developing scalable ETL solutions, managing large-scale data platforms, and ensuring data quality and accessibility. Proven ability to leverage Big Data technologies and cloud platforms to drive critical business intelligence and operational efficiency. Adept at collaborating with cross-functional teams to deliver impactful data products.
Data Pipeline Engineer salary by country
| Country | 25th percentile | Median | 75th percentile |
|---|---|---|---|
| US | $141,238 | $160,720 | $180,202 |
| UK | £61,667 | £76,296 | £86,526 |
| Canada | C$124,167 | C$138,333 | C$146,292 |
| Australia | A$101,935 | A$126,667 | A$147,857 |
| Germany | €59,500 | €70,570 | €77,887 |
| France | €37,875 | €44,167 | €49,750 |
| Netherlands | €55,000 | €66,667 | €74,250 |
| Italy | €25,000 | €31,250 | €38,750 |
| Austria | €46,250 | €58,750 | €67,500 |
| New Zealand | NZ$102,500 | NZ$120,000 | NZ$162,500 |
| India | ₹1,147,059 | ₹1,882,353 | ₹2,807,692 |
| Poland | zł186,440 | zł209,338 | zł232,236 |
Annual salaries in local currency, aggregated from live job postings via Adzuna. Figures refresh continuously and reflect advertised pay, not negotiated offers.
Data Pipeline Engineer resume skills and keywords
Recruiters and applicant tracking systems scan Data Pipeline Engineer resumes for these skills and keywords. Include the ones that match your experience and mirror the wording in the job description. Check your resume against them with the free ATS checker.
Hard skills
Tools & software
Certifications
Soft skills
Market Insights
Data Pipeline Engineer
Salary Range
Salary Trend
Mar 2025 – Feb 2026
12-Month Trend
Based on advertised Software Engineering roles.
US market data · Source: Adzuna · Updated Mar 2026
Frequently Asked Questions
What's the best resume structure for a mid-level Data Pipeline Engineer?
What key skills should a Data Pipeline Engineer emphasize on their resume?
How do I write strong achievement bullets and a professional summary?
What optional sections are beneficial for a Data Pipeline Engineer?
How can I tailor my resume for a specific Data Pipeline Engineer role?
The blank page is the hard part. Skip it.
Free to use. No download fee.
Related Articles

How to Write a CV for Tech Applications [2026 Guide]
Learn how to write a software engineering CV that gets interviews. Real template analysis, what hiring managers look for, and common mistakes to avoid.

How to Write a CV That Shows Startup Experience [2026 Guide]
Learn how to write a CV that showcases founding engineer and startup experience. Real example from JobSprout's creator, what hiring managers look for, and how to position breadth as a strength.