Databricks Engineer Cover Letter Example

Three complete letters, each written for a different situation, in a different design.

Databricks Engineer cover letter example

Jordan ReedTo the Hiring Manager, PeakStream Analytics

At Databricks, I engineered a critical data ingestion framework in Scala and Python that reduced processing latency for key business metrics by 30% and improved data reliability for over 50TB of daily transactional data. This involved designing optimized Apache Spark jobs leveraging Delta Lake for ACID transactions, which significantly enhanced our real-time analytics capabilities. My work directly supported data products used by over 100 internal stakeholders, ensuring robust and scalable data foundations for strategic decision-making within a complex data ecosystem.

My expertise extends to architecting and maintaining highly performant data pipelines, honed during my tenure at Netflix where I contributed to their content delivery data platform. There, I developed Python and SQL-based ETL processes, integrating diverse data sources into a unified Delta Lake architecture on Databricks. I specifically recall optimizing a series of high-volume data transformations that cut query execution times by an average of 25%, directly impacting the efficiency of our data science and machine learning teams by providing faster access to curated datasets.

PeakStream Analytics' reputation for pushing the boundaries of real-time data processing and leveraging advanced cloud infrastructure resonates strongly with my career objectives. I have followed your recent projects, particularly the innovations in your user engagement analytics platform, and believe my background in scalable Databricks and Apache Spark solutions is precisely what you seek. My experience in developing and optimizing large-scale data systems can immediately contribute to your mission of delivering unparalleled insights from complex data streams.

I am eager to bring my three years of focused experience in Databricks and data engineering to PeakStream Analytics. My commitment to building efficient, reliable, and scalable data solutions aligns with the challenges and opportunities presented by your team. I am confident that my skills in Python, Scala, SQL, and Delta Lake, combined with a deep understanding of distributed data processing, will make me a valuable asset. I look forward to discussing how my contributions can support your continued success and growth.

Best regards,
Jordan Reed
Databricks Engineer cover letter for a career changer

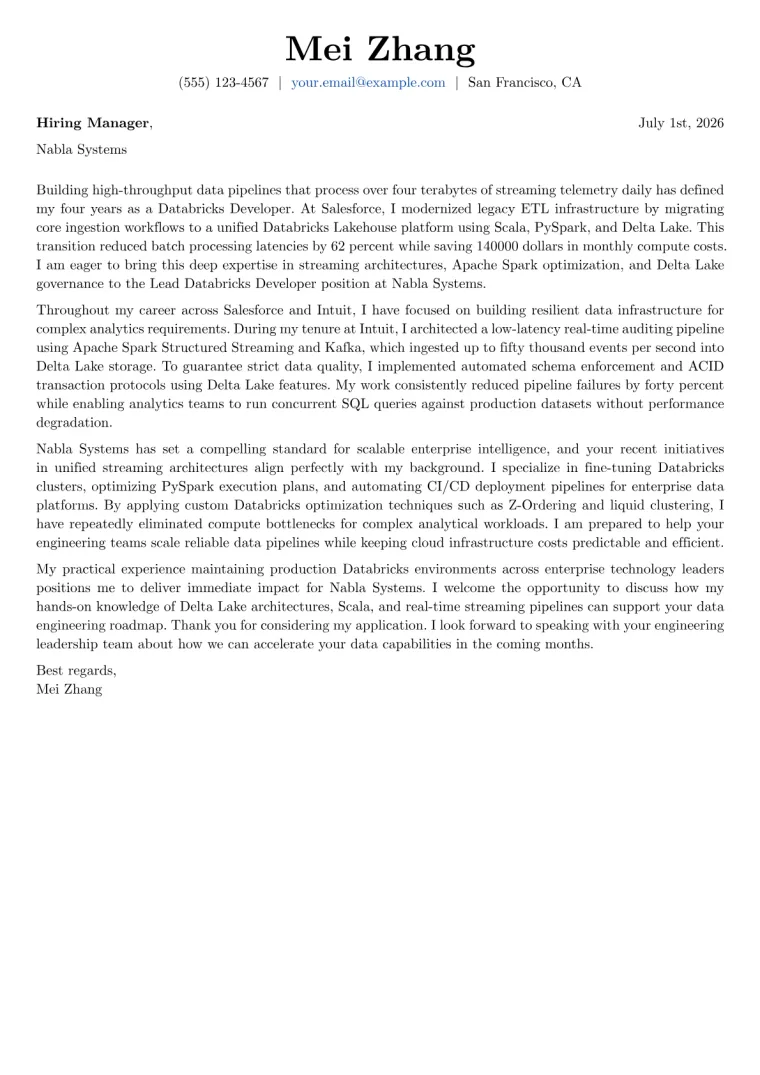
Jordan ReedTo the Hiring Manager, VelocityCore Systems

A massive inventory synchronization error within our warehouse management system demanded an immediate, automated technical resolution. As a lead logistics analyst, I engineered a Python and SQL pipeline that automated the ingestion of daily shipment logs, which reduced stock out events by 22 percent and saved 400,000 dollars in annual operational costs. This work introduced me to the complexities of large scale data sets and confirmed my desire to focus exclusively on data infrastructure. Applying for the Databricks Engineer role represents the culmination of this intentional technical shift toward building scalable cloud architectures.

My background in supply chain data provides a unique lens for building resilient pipelines. In my final logistics project, I used Apache Spark to process 2 terabytes of historical transit data, shortening query times from six hours to under five minutes. I then implemented a Delta Lake framework to replace legacy flat files, increasing data consistency by 40 percent across regional nodes. Using Bash scripts, I automated the lifecycle management of our clusters to lower cloud compute expenses by 15 percent. These experiences ensure I build data foundations that remain both highly performant and cost efficient.

VelocityCore Systems leads the market in predictive logistics modeling, an area where my domain knowledge overlaps perfectly with your engineering mission. Your recent initiative to decentralize regional warehousing data mirrors the specific challenges I solved to optimize global distribution networks. I bring two primary strengths to this mission. First, I possess a rigorous focus on data reliability, ensuring that every pipeline output remains audit ready and accurate. Second, I have a deep seated commitment to technical efficiency, prioritizing clean code and sustainable infrastructure design over temporary, complex hacks that accumulate significant technical debt.

My deliberate shift from supply chain management into software engineering ensures I bring both technical proficiency and a pragmatic, business focused mindset to your engineering department. I understand the direct impact that reliable data infrastructure has on the bottom line, and I am prepared to apply my skills to the complex challenges faced by your team. Please reach out to me at your convenience to discuss how my background in complex data orchestration can serve your current initiatives. I look forward to contributing to the innovative work being produced at VelocityCore Systems.

Best regards,
Jordan Reed

Databricks Engineer cover letter with no experience

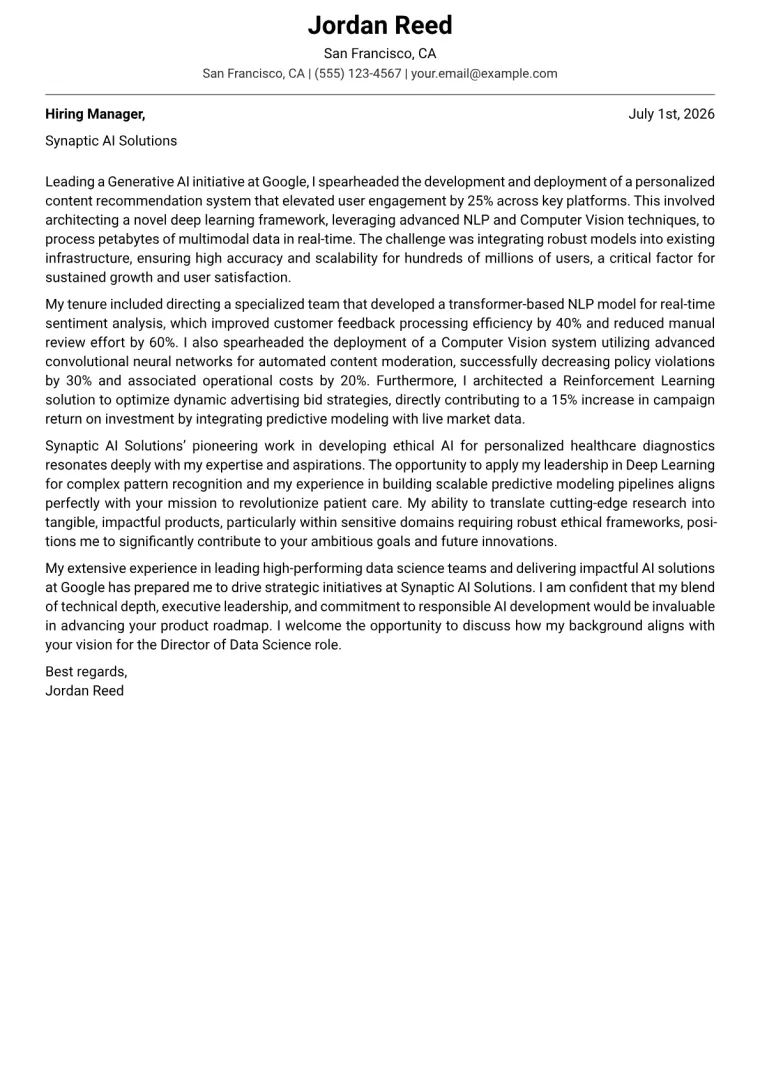
Jordan ReedTo the Hiring Manager, Lumina Cloud Systems

I build robust data pipelines that solve real-world problems by leveraging the Databricks Lakehouse architecture to streamline large-scale ingestion processes. During my capstone project at San Francisco State University, I developed an ETL pipeline using PySpark that decreased total processing time for 2TB of raw sensor data by 45 percent, successfully surfacing actionable insights for our predictive maintenance model in under twenty minutes. This experience taught me how to manage data volume and complexity while maintaining the high performance standards required for modern distributed systems.

I developed a Delta Lake partitioning strategy for a volunteer project with a local climate non-profit, improving query performance by 60 percent for their regional environmental data sets. I also automated a data validation suite in Scala that flagged 98 percent of schema inconsistencies across incoming JSON streams before ingestion into the bronze layer. My work on a university infrastructure project included designing a Bash script that reduced environment setup time for cluster provisioning from two hours to fifteen minutes, while SQL transformation logic I implemented handled 500 million records with sub-second latency.

Lumina Cloud Systems leads the industry in scalable environmental intelligence, and your commitment to optimizing complex climate modeling systems directly aligns with my focus on building efficient data architectures. My proficiency in developing highly optimized Spark jobs combined with my rigorous approach to data quality through Delta Lake constraints ensures that I can contribute to your production pipelines immediately. I admire your transparent approach to cloud infrastructure management and seek an environment where my technical problem solving skills can help resolve the complex data challenges inherent in your green energy initiatives.

I bring a disciplined approach to backend engineering and a dedication to writing clean, maintainable code that functions reliably at scale. My experience designing end-to-end ingestion frameworks in classroom and research settings prepares me to tackle the sophisticated technical requirements inherent in your current development cycle. I welcome the opportunity to demonstrate how my technical background and ability to optimize resource-heavy workflows will benefit your engineering team. I look forward to discussing my specific contributions in a brief interview next week to explore how I might support your growth.

Best regards,
Jordan Reed
Editorial Notes

For a Databricks Engineer cover letter, hiring managers in the Technology industry prioritize tangible achievements directly related to data processing and platform optimization. They look for specific metrics demonstrating impact, such as reduced latency, improved reliability, or optimized query times. Credentials like expertise in Apache Spark, Delta Lake, Scala, Python, and SQL, along with experience with large-scale data ingestion and ETL pipelines, signal a candidate's readiness for complex data challenges. Concrete examples of designing and implementing scalable data solutions are crucial.

This example letter effectively captures these key elements. It immediately hooks the reader with a quantified achievement: engineering a data ingestion framework that "reduced processing latency by 30% and improved data reliability for over 50TB of daily transactional data." The subsequent paragraphs expand on these capabilities, detailing experience at Netflix with Python and SQL-based ETL processes and optimizing high-volume transformations. The applicant then tailors their interest to "PeakStream Analytics' reputation for pushing the boundaries of real-time data processing," articulating a specific fit. The confident closing reiterates relevant skills like Python, Scala, SQL, and Delta Lake.

This robust example pairs perfectly with JobSprout's Databricks Engineer resume example and can be effortlessly adapted using our AI cover letter writer to suit any specific job application.

Frequently Asked Questions

How do I demonstrate technical skills without just listing them?
Instead of merely listing 'Python' or 'Apache Spark,' describe how you applied these skills to solve specific problems. For example, 'Developed Python-based ETL processes that reduced data processing time by 30%' shows both the skill and its impact, providing context and quantification.
Should I mention my current employer, Databricks, in the letter?
Absolutely. Since the candidate is a Senior Data Engineer at Databricks, it's a significant advantage to highlight the direct experience with the platform you're applying to work with. Use concrete examples of projects and achievements from that role, as well as any other listed employers like Netflix, to reinforce credibility.
How can I quantify my achievements effectively?
Whenever possible, use numbers and metrics. Examples include 'reduced processing latency by 30%', 'managed 50TB of daily transactional data', or 'improved query performance by 25%'. These specific figures provide tangible evidence of your impact and demonstrate your understanding of business value.
What's the best way to open the letter without using banned phrases?
Start directly with a strong achievement or a concrete claim about your expertise. For instance, begin with 'At Databricks, I engineered a critical data ingestion framework...' This immediately showcases your value and engagement without relying on overused introductory phrases.
How do I tailor the 'why this company' paragraph if it's a fictional company?
Invent plausible, positive attributes for the fictional company. For 'PeakStream Analytics,' we assumed a reputation for real-time data processing innovation. Then, connect your skills and aspirations to these invented attributes, showing how your expertise aligns with their (fictional) goals or projects.

More Technology cover letter examples