Databricks Engineer Resume Example
 Example by JobSprout
Free to use. No download fee.
Market Insights
Databricks Engineer
Salary Range
Salary Trend
12-Month Trend
Based on advertised Data Science & Analytics roles.
US market data · Source: Adzuna · Updated Mar 2026
How useful was this template?
Databricks Engineer resume samples
Three complete resumes, each in a different design.
Free to use. No download fee.
What makes a strong Databricks Engineer resume?
US median salary $145,603 ·
A strong Databricks Engineer resume in the technology sector emphasizes practical achievements in data pipeline development, optimization, and real-time processing. Hiring managers specifically seek candidates who demonstrate expertise with core technologies like Apache Spark, Delta Lake, and cloud platforms, alongside a proven ability to deliver quantifiable impact. Nuances for this role include showcasing experience with real-time ingestion, data quality frameworks, and cost optimization of compute resources. Specific terminology and metrics, such as “Delta Live Tables,” “Apache Kafka,” “reducing latency by 40%,” or “30% reduction in job execution time,” are crucial for highlighting depth of skill and tangible results.
Why this example works
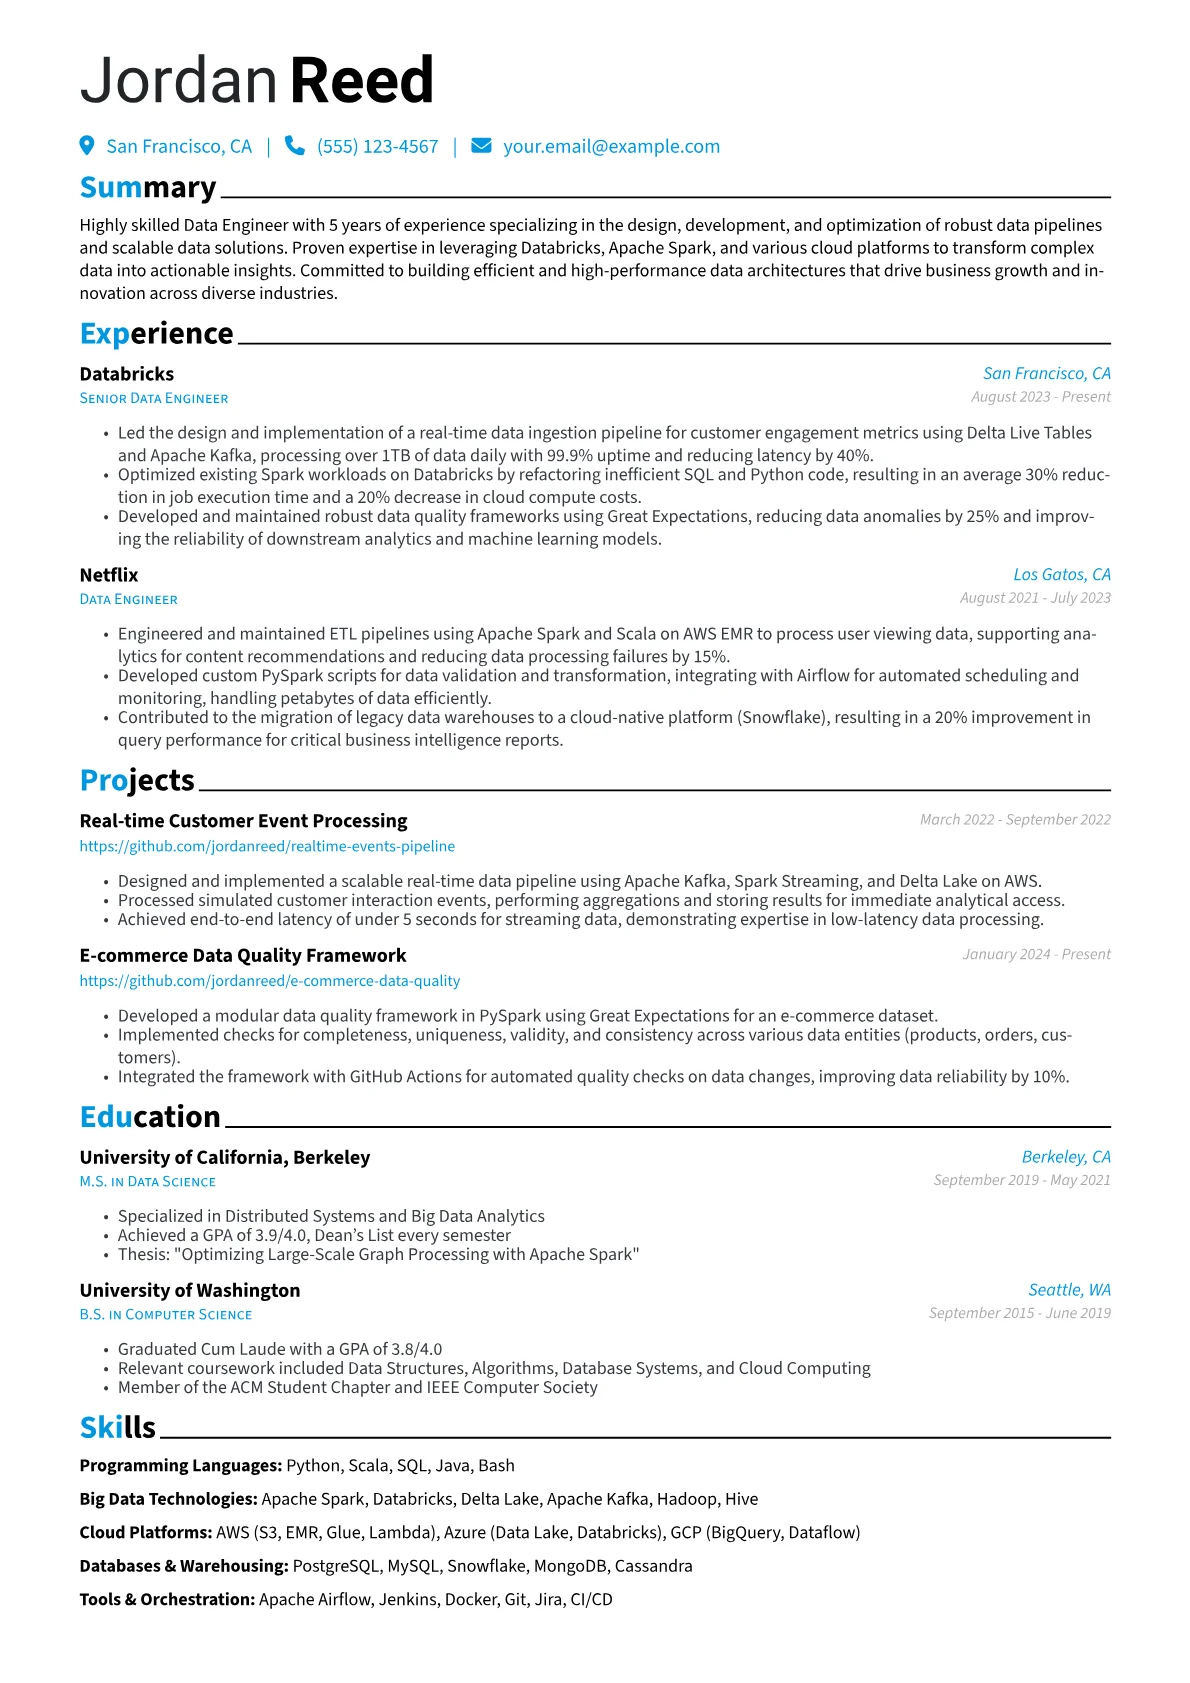
This example resume effectively showcases Jordan Reed's expertise as a Databricks Engineer. The “Experience” section highlights impactful contributions, such as leading the design and implementation of a real-time data ingestion pipeline processing over 1TB daily with 99.9% uptime, and optimizing Spark workloads for a 30% reduction in job execution time and 20% decrease in cloud costs. Furthermore, the resume details work with Great Expectations to reduce data anomalies by 25% and mention of “Apache Spark and Scala on AWS EMR” for ETL pipelines. The “Skills” section is comprehensive, covering “Big Data Technologies” like Databricks and Delta Lake, various “Cloud Platforms,” and “Tools & Orchestration” including Apache Airflow and Docker, providing a well-rounded technical profile.
Databricks Engineer resume example (text version)
Jordan Reed · Databricks Engineer
Summary
Highly skilled Data Engineer with 5 years of experience specializing in the design, development, and optimization of robust data pipelines and scalable data solutions. Proven expertise in leveraging Databricks, Apache Spark, and various cloud platforms to transform complex data into actionable insights. Committed to building efficient and high-performance data architectures that drive business growth and innovation across diverse industries.
Experience
Senior Data Engineer · Databricks
San Francisco, CA · 2023 - Present
- Led the design and implementation of a real-time data ingestion pipeline for customer engagement metrics using Delta Live Tables and Apache Kafka, processing over 1TB of data daily with 99.9% uptime and reducing latency by 40%.
- Optimized existing Spark workloads on Databricks by refactoring inefficient SQL and Python code, resulting in an average 30% reduction in job execution time and a 20% decrease in cloud compute costs.
- Developed and maintained robust data quality frameworks using Great Expectations, reducing data anomalies by 25% and improving the reliability of downstream analytics and machine learning models.
- Collaborated with product teams to define data requirements and build scalable data models in Delta Lake for new features, improving data accessibility for 50+ internal users and enabling faster decision-making.
Data Engineer · Netflix
Los Gatos, CA · 2021 - 2023
- Engineered and maintained ETL pipelines using Apache Spark and Scala on AWS EMR to process user viewing data, supporting analytics for content recommendations and reducing data processing failures by 15%.
- Developed custom PySpark scripts for data validation and transformation, integrating with Airflow for automated scheduling and monitoring, handling petabytes of data efficiently.
- Contributed to the migration of legacy data warehouses to a cloud-native platform (Snowflake), resulting in a 20% improvement in query performance for critical business intelligence reports.
- Implemented robust monitoring and alerting for data pipelines using Datadog, decreasing incident response time by 30% and ensuring high data availability.
Education
M.S. in Data Science · University of California, Berkeley
Berkeley, CA · 2019 - 2021
- Specialized in Distributed Systems and Big Data Analytics
- Achieved a GPA of 3.9/4.0, Dean's List every semester
- Thesis: "Optimizing Large-Scale Graph Processing with Apache Spark"
B.S. in Computer Science · University of Washington
Seattle, WA · 2015 - 2019
- Graduated Cum Laude with a GPA of 3.8/4.0
- Relevant coursework included Data Structures, Algorithms, Database Systems, and Cloud Computing
- Member of the ACM Student Chapter and IEEE Computer Society
Skills
Databricks Engineer resume example: Alternate Version
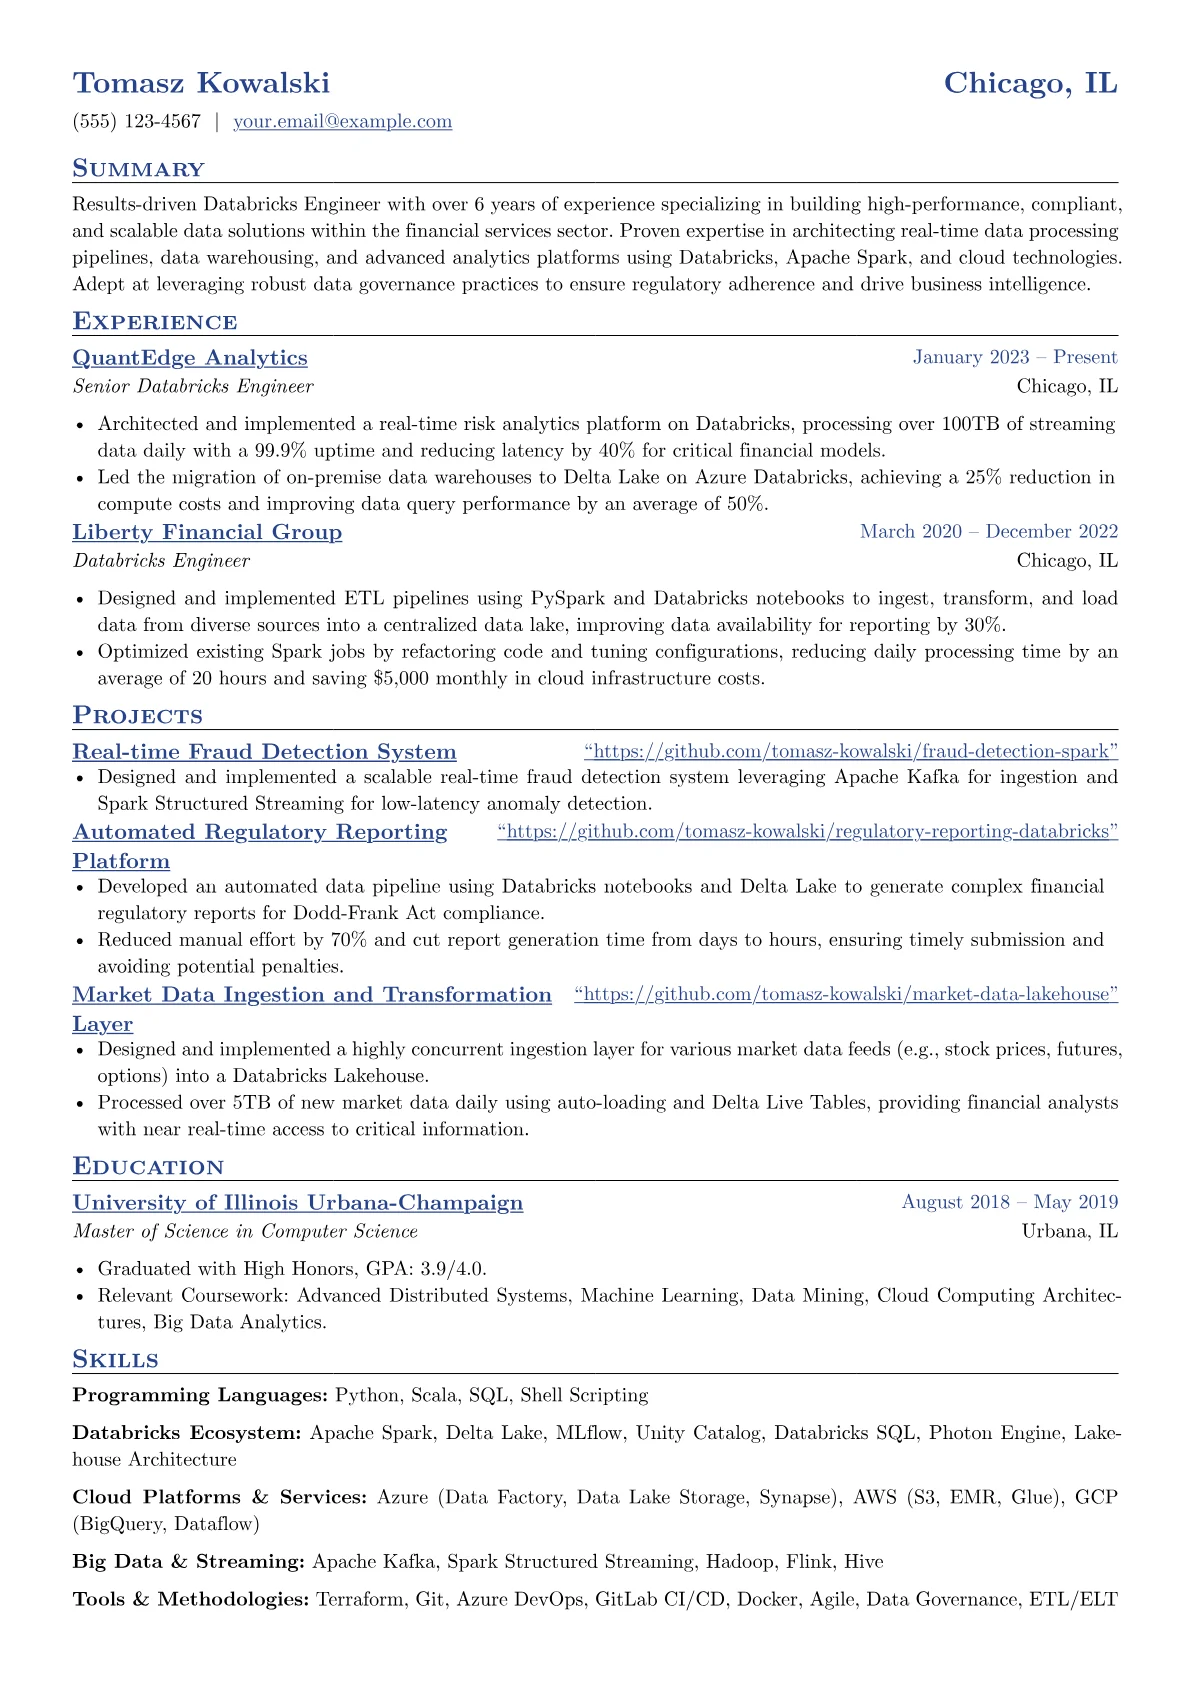
Tomasz Kowalski · Databricks Engineer
Summary
Results-driven Databricks Engineer with over 6 years of experience specializing in building high-performance, compliant, and scalable data solutions within the financial services sector. Proven expertise in architecting real-time data processing pipelines, data warehousing, and advanced analytics platforms using Databricks, Apache Spark, and cloud technologies. Adept at leveraging robust data governance practices to ensure regulatory adherence and drive business intelligence.
Experience
Senior Databricks Engineer · QuantEdge Analytics
Chicago, IL · 2023 - Present
- Architected and implemented a real-time risk analytics platform on Databricks, processing over 100TB of streaming data daily with a 99.9% uptime and reducing latency by 40% for critical financial models.
- Led the migration of on-premise data warehouses to Delta Lake on Azure Databricks, achieving a 25% reduction in compute costs and improving data query performance by an average of 50%.
- Developed and enforced data governance policies using Unity Catalog, ensuring 100% compliance with financial regulations (e.g., SOX, GDPR) across 50+ critical data assets.
- Mentored a team of 4 junior data engineers, fostering best practices in Spark optimization, CI/CD pipelines (Azure DevOps), and Databricks workspace management, enhancing team productivity by 15%.
Databricks Engineer · Liberty Financial Group
Chicago, IL · 2020 - 2022
- Designed and implemented ETL pipelines using PySpark and Databricks notebooks to ingest, transform, and load data from diverse sources into a centralized data lake, improving data availability for reporting by 30%.
- Optimized existing Spark jobs by refactoring code and tuning configurations, reducing daily processing time by an average of 20 hours and saving $5,000 monthly in cloud infrastructure costs.
- Collaborated with data scientists to deploy machine learning models (MLflow) for credit risk assessment, resulting in a 10% increase in model accuracy and a 5% decrease in default rates.
- Developed robust data quality checks and monitoring frameworks within Databricks, reducing data discrepancies by 90% and improving overall data reliability.
Education
Master of Science in Computer Science · University of Illinois Urbana-Champaign
Urbana, IL · 2018 - 2019
- Graduated with High Honors, GPA: 3.9/4.0.
- Relevant Coursework: Advanced Distributed Systems, Machine Learning, Data Mining, Cloud Computing Architectures, Big Data Analytics.
- Master's Thesis: "Optimizing Low-Latency Data Streaming Architectures on Apache Spark" focusing on financial transaction processing.
Skills
Databricks Engineer resume example: Career Changer
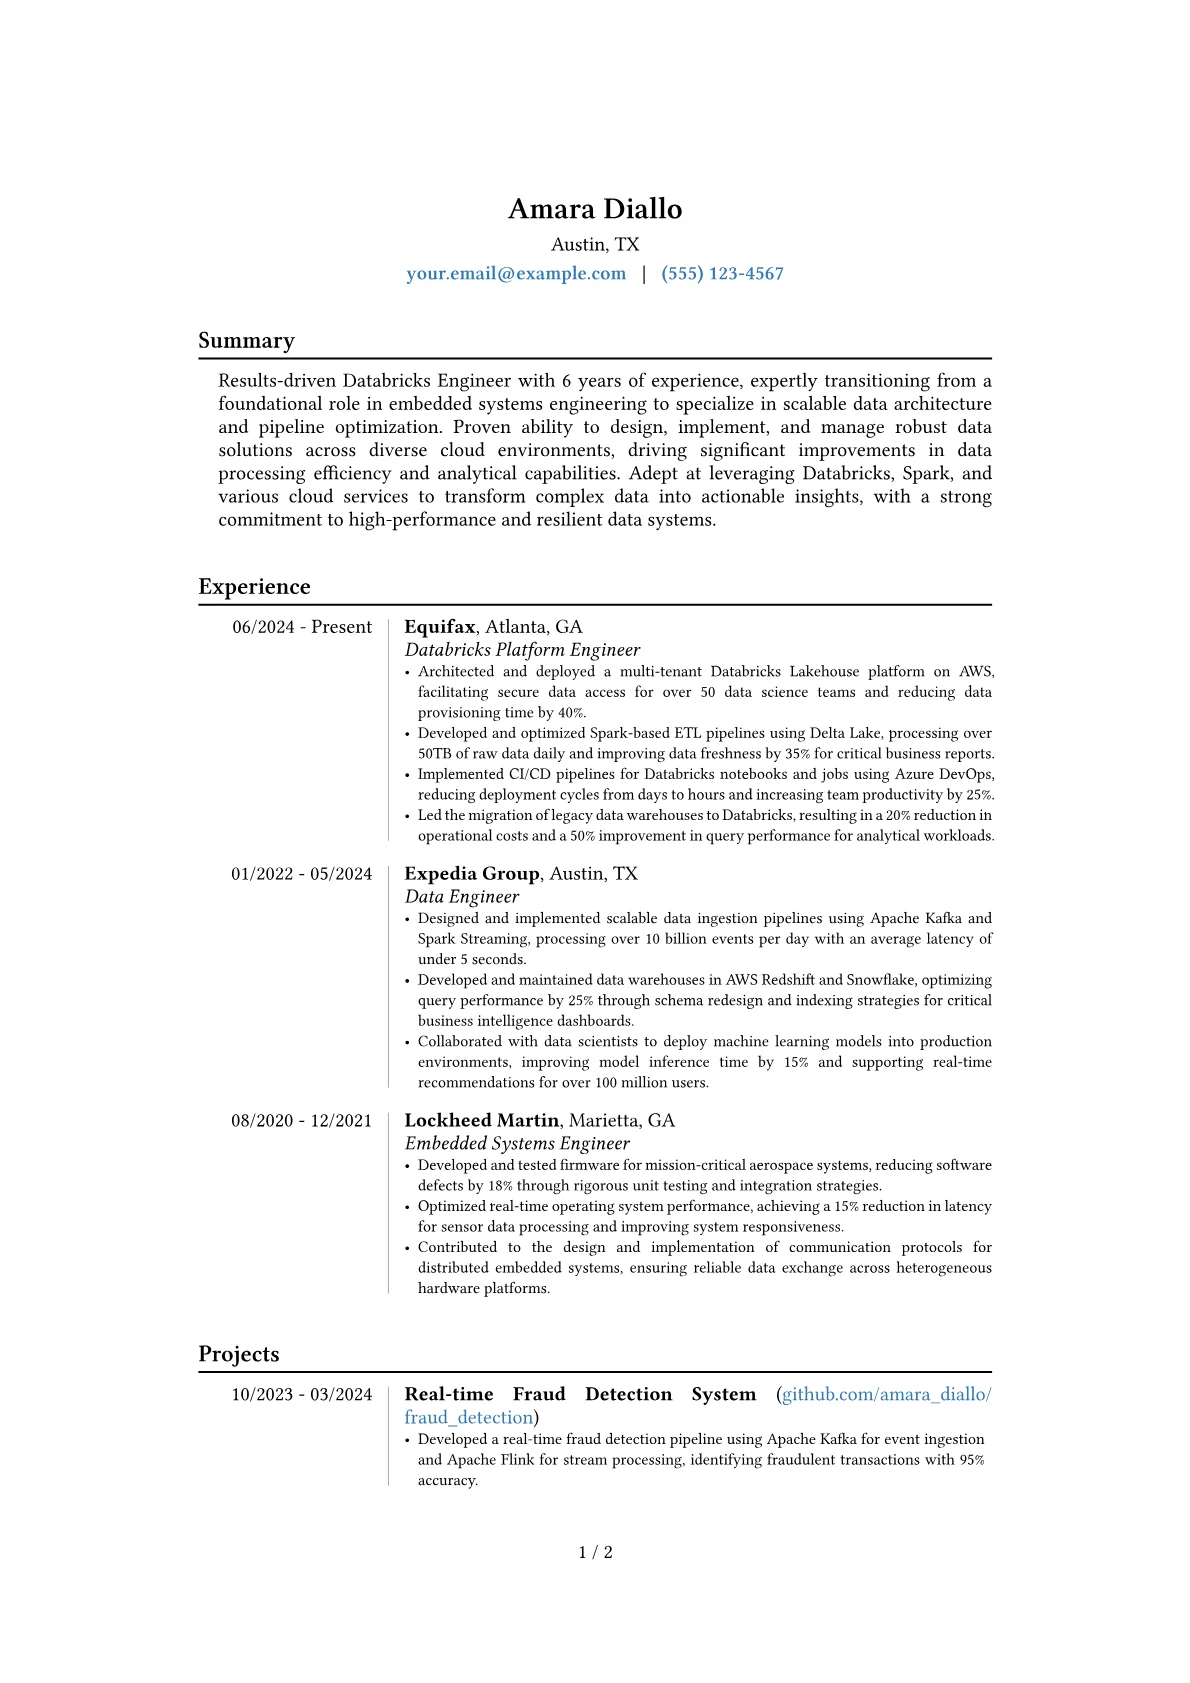
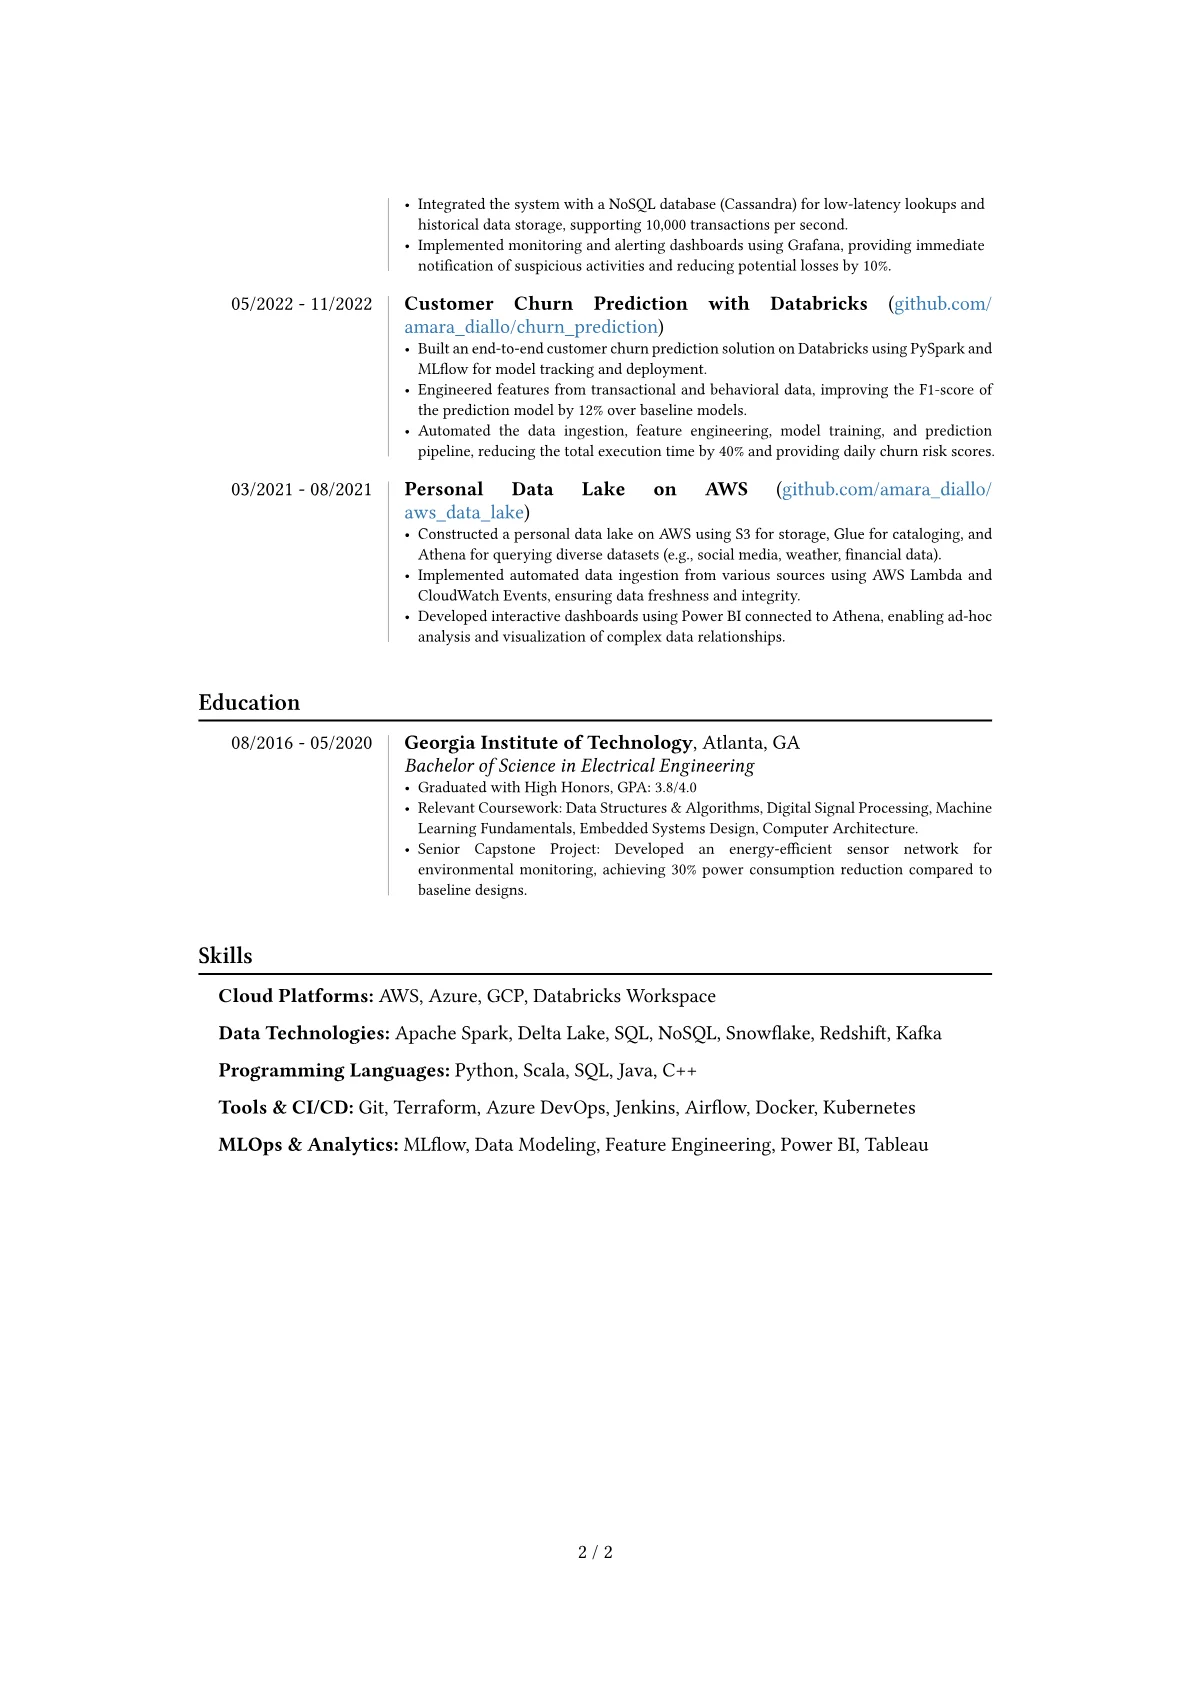
Amara Diallo · Databricks Engineer
Summary
Results-driven Databricks Engineer with 6 years of experience, expertly transitioning from a foundational role in embedded systems engineering to specialize in scalable data architecture and pipeline optimization. Proven ability to design, implement, and manage robust data solutions across diverse cloud environments, driving significant improvements in data processing efficiency and analytical capabilities. Adept at leveraging Databricks, Spark, and various cloud services to transform complex data into actionable insights, with a strong commitment to high-performance and resilient data systems.
Experience
Databricks Platform Engineer · Equifax
Atlanta, GA · 2024 - Present
- Architected and deployed a multi-tenant Databricks Lakehouse platform on AWS, facilitating secure data access for over 50 data science teams and reducing data provisioning time by 40%.
- Developed and optimized Spark-based ETL pipelines using Delta Lake, processing over 50TB of raw data daily and improving data freshness by 35% for critical business reports.
- Implemented CI/CD pipelines for Databricks notebooks and jobs using Azure DevOps, reducing deployment cycles from days to hours and increasing team productivity by 25%.
- Led the migration of legacy data warehouses to Databricks, resulting in a 20% reduction in operational costs and a 50% improvement in query performance for analytical workloads.
Data Engineer · Expedia Group
Austin, TX · 2022 - 2024
- Designed and implemented scalable data ingestion pipelines using Apache Kafka and Spark Streaming, processing over 10 billion events per day with an average latency of under 5 seconds.
- Developed and maintained data warehouses in AWS Redshift and Snowflake, optimizing query performance by 25% through schema redesign and indexing strategies for critical business intelligence dashboards.
- Collaborated with data scientists to deploy machine learning models into production environments, improving model inference time by 15% and supporting real-time recommendations for over 100 million users.
Embedded Systems Engineer · Lockheed Martin
Marietta, GA · 2020 - 2021
- Developed and tested firmware for mission-critical aerospace systems, reducing software defects by 18% through rigorous unit testing and integration strategies.
- Optimized real-time operating system performance, achieving a 15% reduction in latency for sensor data processing and improving system responsiveness.
- Contributed to the design and implementation of communication protocols for distributed embedded systems, ensuring reliable data exchange across heterogeneous hardware platforms.
Education
Bachelor of Science in Electrical Engineering · Georgia Institute of Technology
Atlanta, GA · 2016 - 2020
- Graduated with High Honors, GPA: 3.8/4.0
- Relevant Coursework: Data Structures & Algorithms, Digital Signal Processing, Machine Learning Fundamentals, Embedded Systems Design, Computer Architecture.
- Senior Capstone Project: Developed an energy-efficient sensor network for environmental monitoring, achieving 30% power consumption reduction compared to baseline designs.
Skills
How useful was this template?
Example by JobSproutDatabricks Engineer resume summary example
Highly skilled Data Engineer with 5 years of experience specializing in the design, development, and optimization of robust data pipelines and scalable data solutions. Proven expertise in leveraging Databricks, Apache Spark, and various cloud platforms to transform complex data into actionable insights. Committed to building efficient and high-performance data architectures that drive business growth and innovation across diverse industries.
Databricks Engineer salary by country
| Country | 25th percentile | Median | 75th percentile |
|---|---|---|---|
| US | $119,566 | $145,603 | $157,773 |
| UK | £49,243 | £69,815 | £72,749 |
| Canada | C$105,216 | C$131,793 | C$148,123 |
| Australia | A$131,111 | A$149,029 | A$159,865 |
| Germany | €64,167 | €74,500 | €83,724 |
| France | €43,872 | €49,698 | €58,304 |
| Netherlands | €56,389 | €70,245 | €71,858 |
| Italy | €38,500 | €62,500 | €71,250 |
| Austria | €45,000 | €70,000 | €85,000 |
| New Zealand | NZ$140,000 | NZ$157,143 | NZ$171,429 |
| India | ₹1,077,818 | ₹1,661,896 | ₹2,459,866 |
| Poland | zł216,083 | zł261,510 | zł306,936 |
Annual salaries in local currency, aggregated from live job postings via Adzuna. Figures refresh continuously and reflect advertised pay, not negotiated offers.
Databricks Engineer resume skills and keywords
Recruiters and applicant tracking systems scan Databricks Engineer resumes for these skills and keywords. Include the ones that match your experience and mirror the wording in the job description. Check your resume against them with the free ATS checker.
Hard skills
Tools & software
Certifications
Soft skills
Market Insights
Databricks Engineer
Salary Range
Salary Trend
12-Month Trend
Based on advertised Data Science & Analytics roles.
US market data · Source: Adzuna · Updated Mar 2026
Frequently Asked Questions
What's the best resume structure for a mid-level Databricks Engineer?
Which Databricks related skills and tools should I highlight on my resume?
How can I effectively describe my Databricks projects and impact?
Should I include a projects section or list specific Databricks certifications?
How can JobSprout's AI assist in tailoring my Databricks resume for different jobs?
The blank page is the hard part. Skip it.
Free to use. No download fee.
Related Articles
Data Scientist Resume: Examples & Guide for 2026
Write a data scientist resume that lands interviews. Resume examples, technical skills formatting, bullet point formulas, and ATS tips for every experience level.
Business Analyst Resume: Examples, Templates & Writing Guide (2026)
Write a business analyst resume that lands interviews. BA resume examples, bullet point formulas for requirements gathering and stakeholder management, skills tables, and ATS tips for every experience level.
How to Write a CV for Tech Applications [2026 Guide]
Learn how to write a software engineering CV that gets interviews. Real template analysis, what hiring managers look for, and common mistakes to avoid.