Kafka Engineer Resume Example

TechnologySoftware EngineeringMid Level (3-5 years)SoftwareEngineering

Free to use. No download fee.

Kafka Engineer resume samples

Three complete resumes, each in a different design.

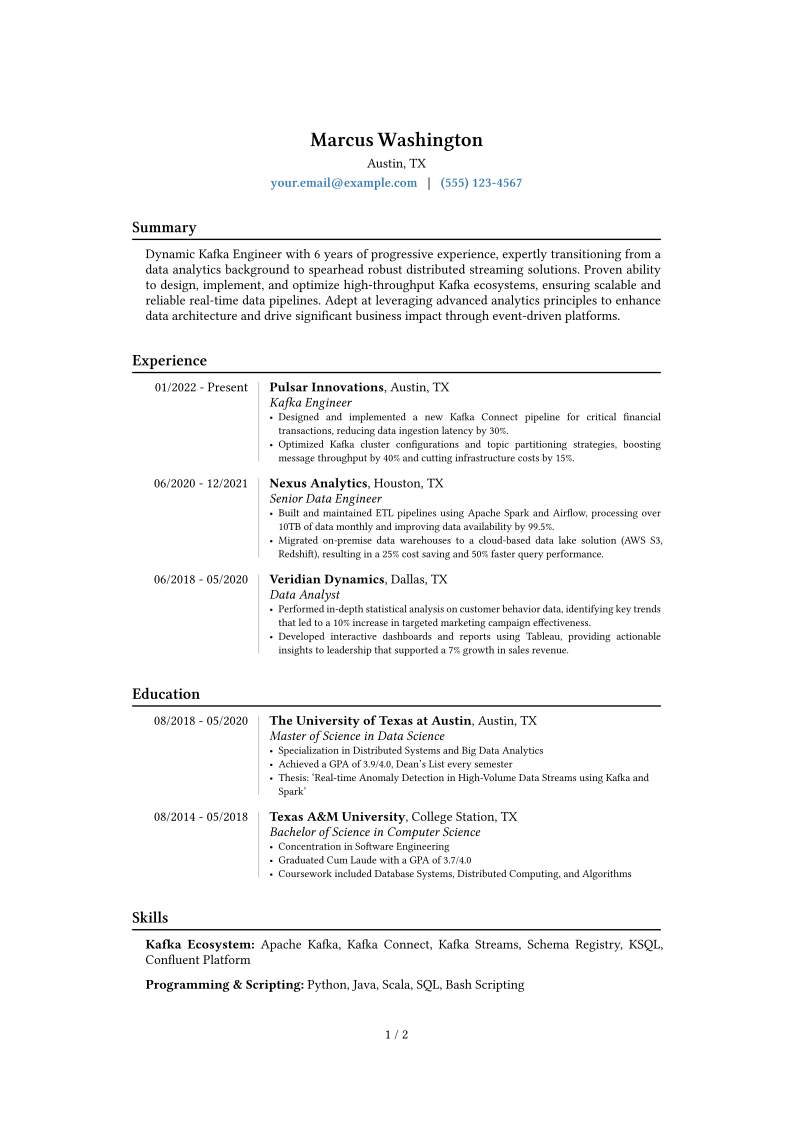
Kafka Engineer resume example, page 1Kafka Engineer resume example, page 2
1 / 2
Kafka Engineer resume example, Core Kafka Ecosystem, page 1
Kafka Engineer resume example, Career changer, page 1Kafka Engineer resume example, Career changer, page 2
1 / 2

Free to use. No download fee.

What makes a strong Kafka Engineer resume?

US median salary $168,704 ·

For Kafka Engineers, hiring managers seek deep expertise in building and maintaining robust, scalable data pipelines. A strong resume highlights hands-on experience with Kafka brokers, Connect, and Streams, demonstrating mastery of distributed systems challenges like ensuring data integrity and low-latency processing. Concrete achievements should quantify impact, such as optimizing Kafka cluster performance to handle petabytes of data or implementing schema management with Avro. Mentioning certifications like Confluent Certified Developer or Administrator, alongside terms like “offset management” and “exactly once processing,” signals specialized knowledge.

Why this example works

This example CV excels at showcasing a Kafka Engineer's capabilities. It groups technical skills clearly, separating “Kafka Ecosystem” components from “Cloud Platforms” and “Programming Languages,” which simplifies scanning for specific expertise. Achievements are quantified effectively, detailing impact like “reduced data processing latency by 25%” or “managed clusters supporting 50 million events daily.” The template prominently displays relevant certifications and specific tools, such as Kafka Streams and Confluent Cloud, making a candidate's specialized experience immediately apparent to recruiters.

Kafka Engineer resume example (text version)

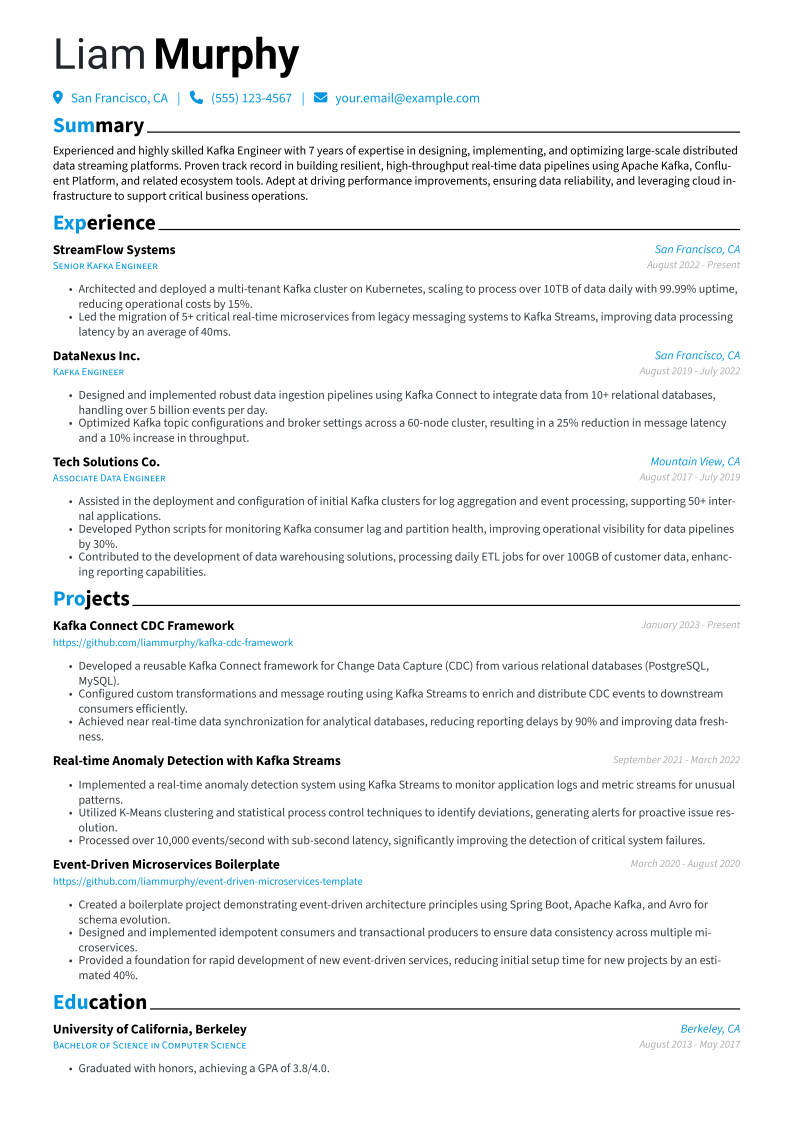
Liam Murphy · Kafka Engineer

Summary

Experienced and highly skilled Kafka Engineer with 7 years of expertise in designing, implementing, and optimizing large-scale distributed data streaming platforms. Proven track record in building resilient, high-throughput real-time data pipelines using Apache Kafka, Confluent Platform, and related ecosystem tools. Adept at driving performance improvements, ensuring data reliability, and leveraging cloud infrastructure to support critical business operations.

Experience

Senior Kafka Engineer · StreamFlow Systems

San Francisco, CA · 2022 - Present

  • Architected and deployed a multi-tenant Kafka cluster on Kubernetes, scaling to process over 10TB of data daily with 99.99% uptime, reducing operational costs by 15%.
  • Led the migration of 5+ critical real-time microservices from legacy messaging systems to Kafka Streams, improving data processing latency by an average of 40ms.
  • Developed and maintained automated CI/CD pipelines for Kafka Connectors and ksqlDB applications, decreasing deployment time by 50% and reducing manual error rates.
  • Implemented advanced monitoring and alerting solutions using Prometheus and Grafana for Kafka clusters, proactively identifying and resolving performance bottlenecks, preventing 3 major outages annually.
  • Mentored junior engineers on best practices for Kafka development, cluster management, and performance tuning, enhancing team's overall productivity by 20%.

Kafka Engineer · DataNexus Inc.

San Francisco, CA · 2019 - 2022

  • Designed and implemented robust data ingestion pipelines using Kafka Connect to integrate data from 10+ relational databases, handling over 5 billion events per day.
  • Optimized Kafka topic configurations and broker settings across a 60-node cluster, resulting in a 25% reduction in message latency and a 10% increase in throughput.
  • Developed custom Kafka Producers and Consumers in Java to ensure exactly-once semantics for critical financial transaction processing, reducing data discrepancies by 99%.
  • Collaborated with data science teams to deliver real-time analytics feeds via Kafka, enabling faster decision-making and contributing to a 5% increase in quarterly revenue.
  • Automated Kafka cluster upgrades and patch deployments using Ansible, reducing maintenance windows by 3 hours per cycle and ensuring seamless service continuity.

Associate Data Engineer · Tech Solutions Co.

Mountain View, CA · 2017 - 2019

  • Assisted in the deployment and configuration of initial Kafka clusters for log aggregation and event processing, supporting 50+ internal applications.
  • Developed Python scripts for monitoring Kafka consumer lag and partition health, improving operational visibility for data pipelines by 30%.
  • Contributed to the development of data warehousing solutions, processing daily ETL jobs for over 100GB of customer data, enhancing reporting capabilities.
  • Implemented data validation routines for incoming data streams, reducing data quality issues by 15% across various systems.
  • Participated in on-call rotations, providing first-line support for data pipeline incidents and resolving issues within defined SLAs.

Education

Bachelor of Science in Computer Science · University of California, Berkeley

Berkeley, CA · 2013 - 2017

  • Graduated with honors, achieving a GPA of 3.8/4.0.
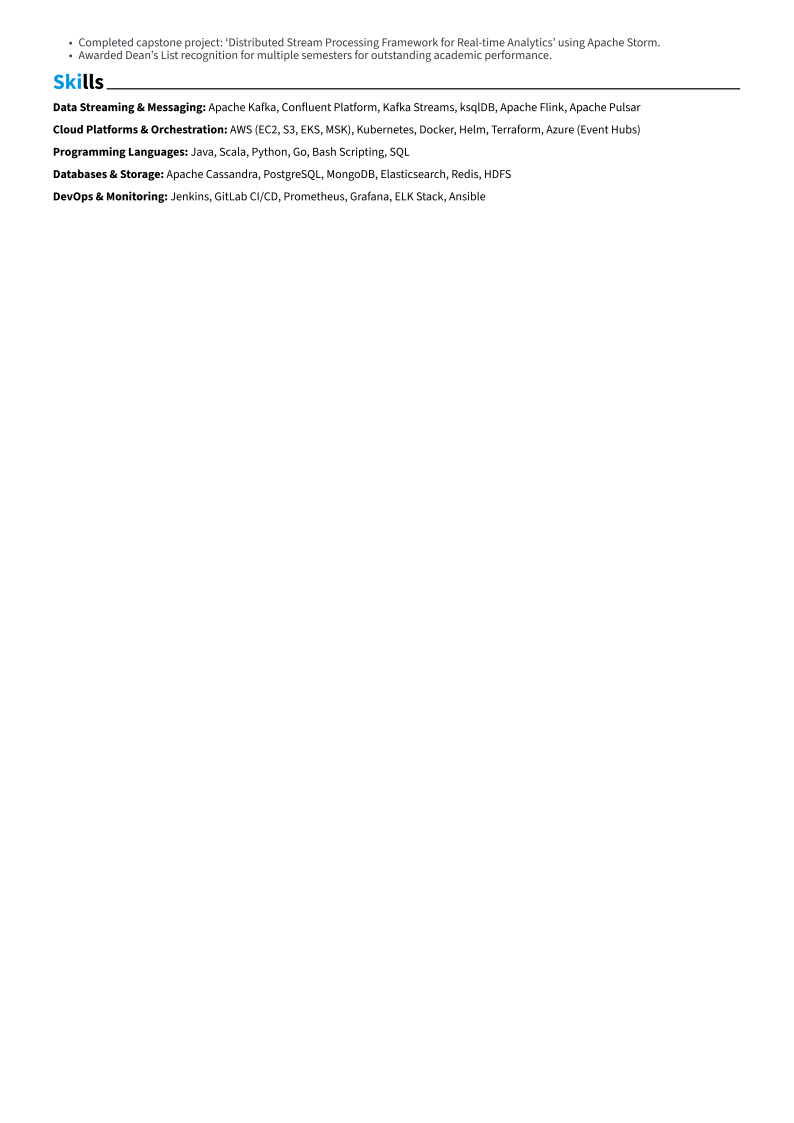
  • Completed capstone project: 'Distributed Stream Processing Framework for Real-time Analytics' using Apache Storm.
  • Awarded Dean's List recognition for multiple semesters for outstanding academic performance.

Skills

Data Streaming & Messaging:Apache KafkaConfluent PlatformKafka StreamsksqlDBApache FlinkApache Pulsar
Cloud Platforms & Orchestration:AWS (EC2, S3, EKS, MSK)KubernetesDockerHelmTerraformAzure (Event Hubs)
Programming Languages:JavaScalaPythonGoBash ScriptingSQL
Databases & Storage:Apache CassandraPostgreSQLMongoDBElasticsearchRedisHDFS
DevOps & Monitoring:JenkinsGitLab CI/CDPrometheusGrafanaELK StackAnsible

How useful was this template?

4.7 (12 votes)
JobSprout logoExample by JobSprout

See this resume as a website

The same content, live on your own jobsprout.me page. Share a link instead of a PDF.

View live example

Kafka Engineer resume summary example

Experienced and highly skilled Kafka Engineer with 7 years of expertise in designing, implementing, and optimizing large-scale distributed data streaming platforms. Proven track record in building resilient, high-throughput real-time data pipelines using Apache Kafka, Confluent Platform, and related ecosystem tools. Adept at driving performance improvements, ensuring data reliability, and leveraging cloud infrastructure to support critical business operations.

Kafka Engineer salary by country

Country25th percentileMedian75th percentile
US$133,125$168,704$219,961
UK£66,250£79,171£102,099
CanadaC$86,152C$113,871C$140,800
AustraliaA$101,935A$126,667A$147,857
Germany€59,500€70,570€77,887
France€37,875€44,167€49,750
Netherlands€55,000€66,667€74,250
Italy€25,000€31,250€38,750
Austria€46,250€58,750€67,500
New ZealandNZ$102,500NZ$120,000NZ$162,500
India₹1,875,000₹2,416,667₹2,875,000
Polandzł212,748zł245,496zł278,244

Annual salaries in local currency, aggregated from live job postings via Adzuna. Figures refresh continuously and reflect advertised pay, not negotiated offers.

Kafka Engineer resume skills and keywords

Recruiters and applicant tracking systems scan Kafka Engineer resumes for these skills and keywords. Include the ones that match your experience and mirror the wording in the job description. Check your resume against them with the free ATS checker.

Hard skills

Apache KafkaKafka StreamsKafka ConnectDistributed SystemsEvent-driven ArchitectureReal-time Data ProcessingData StreamingMicroservices ArchitectureData PipelinesPerformance TuningScalabilityHigh AvailabilitySchema RegistryKSQL

Tools & software

Confluent PlatformKubernetesDockerAWSPrometheusGrafanaGitJenkins

Certifications

CCDAKCCAAKAWS Certified Solutions ArchitectAWS Certified Developer

Soft skills

Problem SolvingCritical ThinkingCross-functional CollaborationCommunication SkillsTechnical Leadership

Market Insights

Kafka Engineer

Salary Range

$168,704median annual
$100k$220k

Salary Trend

12-Month Trend

Stable
+2.4% YoY

Based on advertised Software Engineering roles.

US market data · Source: Adzuna · Updated Mar 2026

Frequently Asked Questions

What's the best resume structure for a mid-level Kafka Engineer?
For a mid-level Kafka Engineer, a technical and results-driven resume in a reverse-chronological format is crucial. Your 'Professional Experience' section should detail your involvement in Kafka-based projects, emphasizing architecture, deployment, and optimization. A prominent 'Technical Skills' section is essential to list specific tools, programming languages, and platforms you are proficient in, providing a clear overview of your capabilities.
What key skills and qualifications should I highlight as a mid-level Kafka Engineer?
Highlight deep expertise in Apache Kafka, including Kafka Connect, Kafka Streams, and ksqlDB. Emphasize experience with distributed systems, real-time data processing, messaging queues, and cloud platforms like AWS, Azure, or GCP. Mention proficiency in programming languages such as Java, Scala, Python, or Go, along with containerization technologies like Docker and Kubernetes to showcase your comprehensive skill set.
How can I write strong achievement bullets or a professional summary for this role?
Your professional summary should concisely state your proven ability to design, implement, and maintain robust Kafka ecosystems. Achievement bullets must be quantitative and demonstrate impact; for example, 'Engineered a Kafka-based data pipeline, processing 10TB of real-time data daily, improving data latency by 30%.' Focus on scalability, performance improvements, and system reliability to clearly demonstrate your technical contributions and value.
Which optional sections matter most for a mid-level Kafka Engineer, like certifications or GitHub projects?
Relevant certifications in cloud platforms, for example, AWS Certified Developer or Azure Data Engineer, or specific Kafka vendor certifications, such as Confluent Certified Developer, are highly valuable. Contributions to open-source projects, a personal GitHub profile showcasing Kafka projects, or technical publications can also strengthen your application. These optional sections provide tangible evidence of your expertise and dedication.
How do I tailor this template for a specific Kafka Engineer job posting?
To tailor your Kafka Engineer resume, closely examine the job description for specific Kafka components, cloud environments, or integration challenges. Prioritize projects and skills that directly address these requirements, showcasing your ability to solve the employer's particular data streaming needs. JobSprout's 'Remix with AI' feature can effectively adapt your resume, highlighting the most relevant technical skills and project experiences after you paste the job description, ensuring a highly targeted application.

The blank page is the hard part. Skip it.

Free to use. No download fee.